The Comparison
Expectations around analytics have shifted, and the tools people rely on have to keep up. Every team has data in spreadsheets and exports — the hard part is turning it into answers without waiting on an analyst. Most questions about the numbers are simple; getting them answered rarely is. Most media & entertainment know the feeling: the answer is somewhere in the files, but reaching it means a queue, a query, or a rebuild. The way a team works with its data says a lot about how quickly it can act.
The Problem
When a backlog of ad-hoc data requests no one can clear in read-from-url data feeds sets in, decisions slow down and the data team drowns in ad-hoc requests. Left unaddressed, a backlog of ad-hoc data requests no one can clear in read-from-url data feeds compounds: questions pile up, reports go stale, and insight stays locked away. It rarely starts as a crisis; a backlog of ad-hoc data requests no one can clear in read-from-url data feeds builds quietly until a board deadline makes it impossible to ignore. A recurring challenge for media & entertainment is a backlog of ad-hoc data requests no one can clear in read-from-url data feeds. For a Associate, Strategy, a backlog of ad-hoc data requests no one can clear in read-from-url data feeds is more than an inconvenience — it is a daily drag on how fast the team can move.
TalkLytx vs Spreadsheets
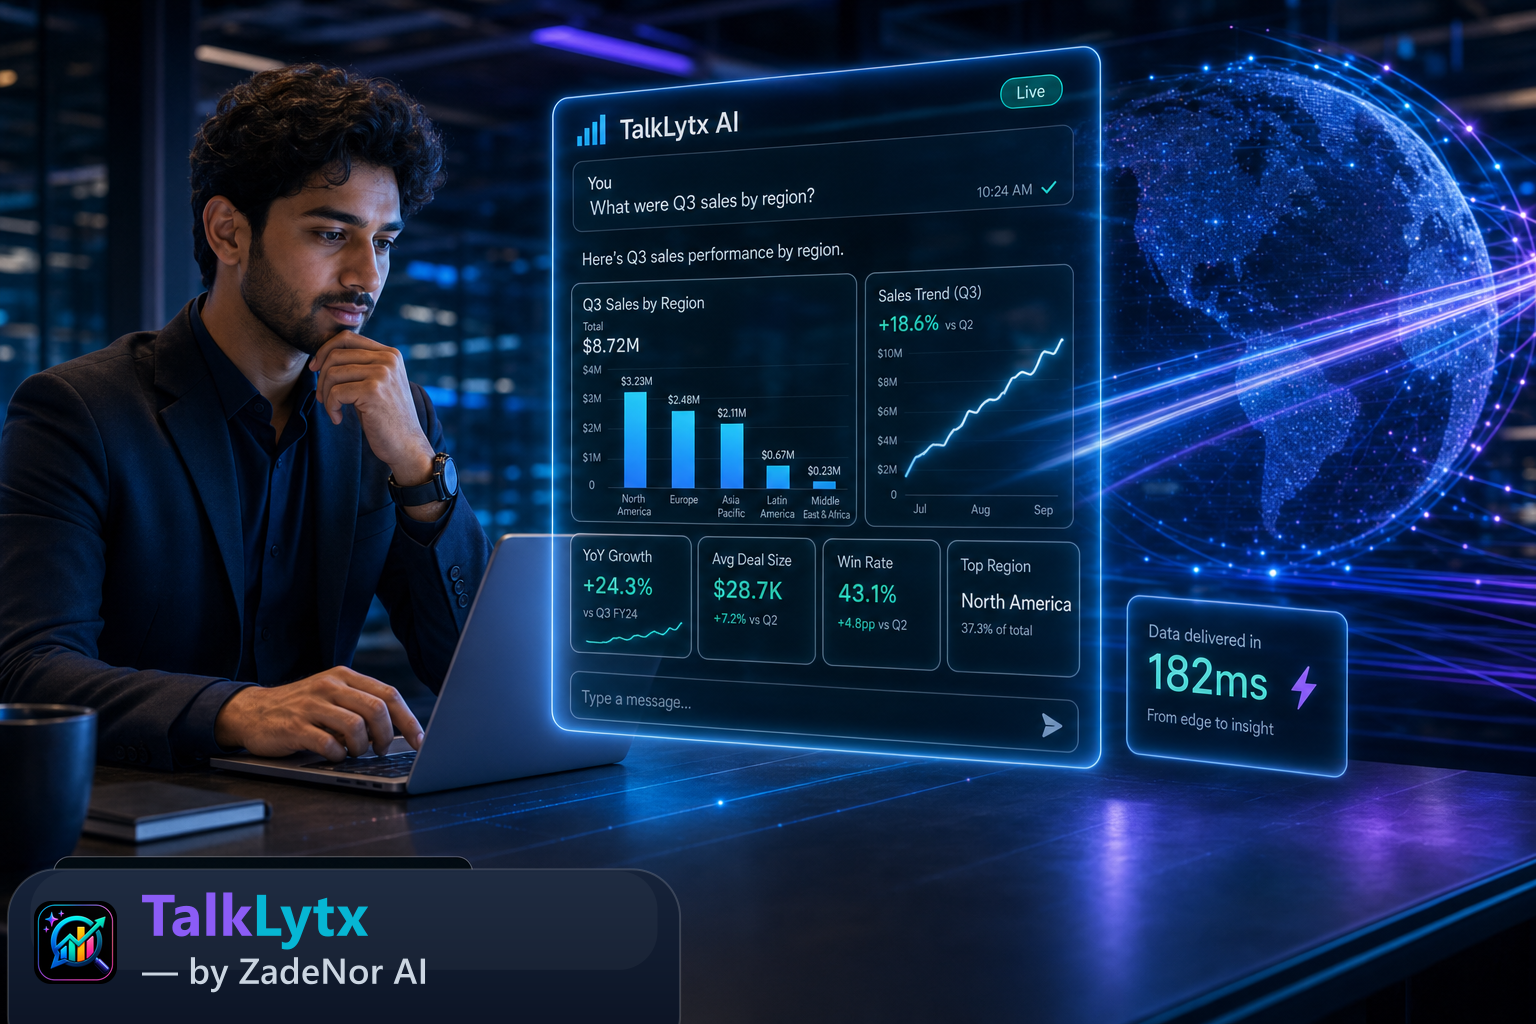
Against a traditional BI queue, conversational analytics absorbs the SQL and the charting without making anyone wait for an analyst. TalkLytx sits in the middle: the ease of asking a question in plain English with the rigour of real, visible SQL and an instant chart. Compared with scattered spreadsheets, the difference is a living workspace — every question, answer and dashboard in one place.
Where TalkLytx Lands
TalkLytx connects natural-language questions, AI-generated SQL, and instant charts, so the whole analysis moves like a conversation. Because the answer, the SQL and the chart arrive together, you work from one transparent source of truth instead of a black box. Rather than another BI tool to learn, TalkLytx lets you upload a file or read from a URL and simply ask your question in plain English. Since shareable answers sits within the Self-Serve capability set, it fits naturally into how media & entertainment already work.
The Better Outcome
You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. For media & entertainment, that means less time wrangling files, more time deciding you can actually rely on. The result is less time wrangling files, more time deciding, without adding headcount or waiting on the queue.
Get Started
Want less time wrangling files, more time deciding with limited analytics staff as a Media & Entertainment? Explore TalkLytx by ZadeNor AI and see how plain-English questions become answers, SQL and charts in seconds. No card required.
What looks like a tooling problem is often an access and trust problem in disguise. The cost of a backlog of ad-hoc data requests no one can clear in read-from-url data feeds is rarely a single number — it is decisions made late, on stale data, or on gut feel. Analytics stops being a bottleneck and starts being a shared, everyday capability. People using this approach see Less time wrangling files, more time deciding with limited analytics staff. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions.
Every hour lost to a backlog of ad-hoc data requests no one can clear in read-from-url data feeds is an hour not spent on the decision the numbers were meant to inform. Teams end up waiting on the BI queue instead of exploring the data themselves. People using this approach see Less time wrangling files, more time deciding with limited analytics staff. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. The result is less time wrangling files, more time deciding, without adding headcount or waiting on the queue.
The cost of a backlog of ad-hoc data requests no one can clear in read-from-url data feeds is rarely a single number — it is decisions made late, on stale data, or on gut feel. Teams end up waiting on the BI queue instead of exploring the data themselves. Over time, a backlog of ad-hoc data requests no one can clear in read-from-url data feeds translates into slower reporting, duplicated work, and insight that never reaches the people who need it. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. For media & entertainment, that means less time wrangling files, more time deciding you can actually rely on.
What looks like a tooling problem is often an access and trust problem in disguise. Every hour lost to a backlog of ad-hoc data requests no one can clear in read-from-url data feeds is an hour not spent on the decision the numbers were meant to inform. Over time, a backlog of ad-hoc data requests no one can clear in read-from-url data feeds translates into slower reporting, duplicated work, and insight that never reaches the people who need it. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. Analytics stops being a bottleneck and starts being a shared, everyday capability.