Ready to Decide
For ml engineering teams, the difference between shipping calmly and firefighting often comes down to how many agents you can run at once and how safely you can merge their work. AI coding agents are powerful, but running more than one at a time usually means chaos in a single shared working tree. Expectations for developer velocity have shifted, and the tools people rely on have to keep up.
The Challenge
It rarely starts as a crisis; no way to queue, prioritize and sequence agent tasks as the team scales builds quietly until a big merge makes it impossible to ignore. When no way to queue, prioritize and sequence agent tasks as the team scales sets in, the day tightens and the risk of a broken build or lost work grows. The issue shows up most clearly as No way to queue, prioritize and sequence agent tasks as the team scales. A recurring challenge for ml engineering teams is no way to queue, prioritize and sequence agent tasks as the team scales. For a Lead DevOps, no way to queue, prioritize and sequence agent tasks as the team scales is more than an inconvenience — it is a daily drag on velocity and peace of mind.
The MergeHarbor Approach
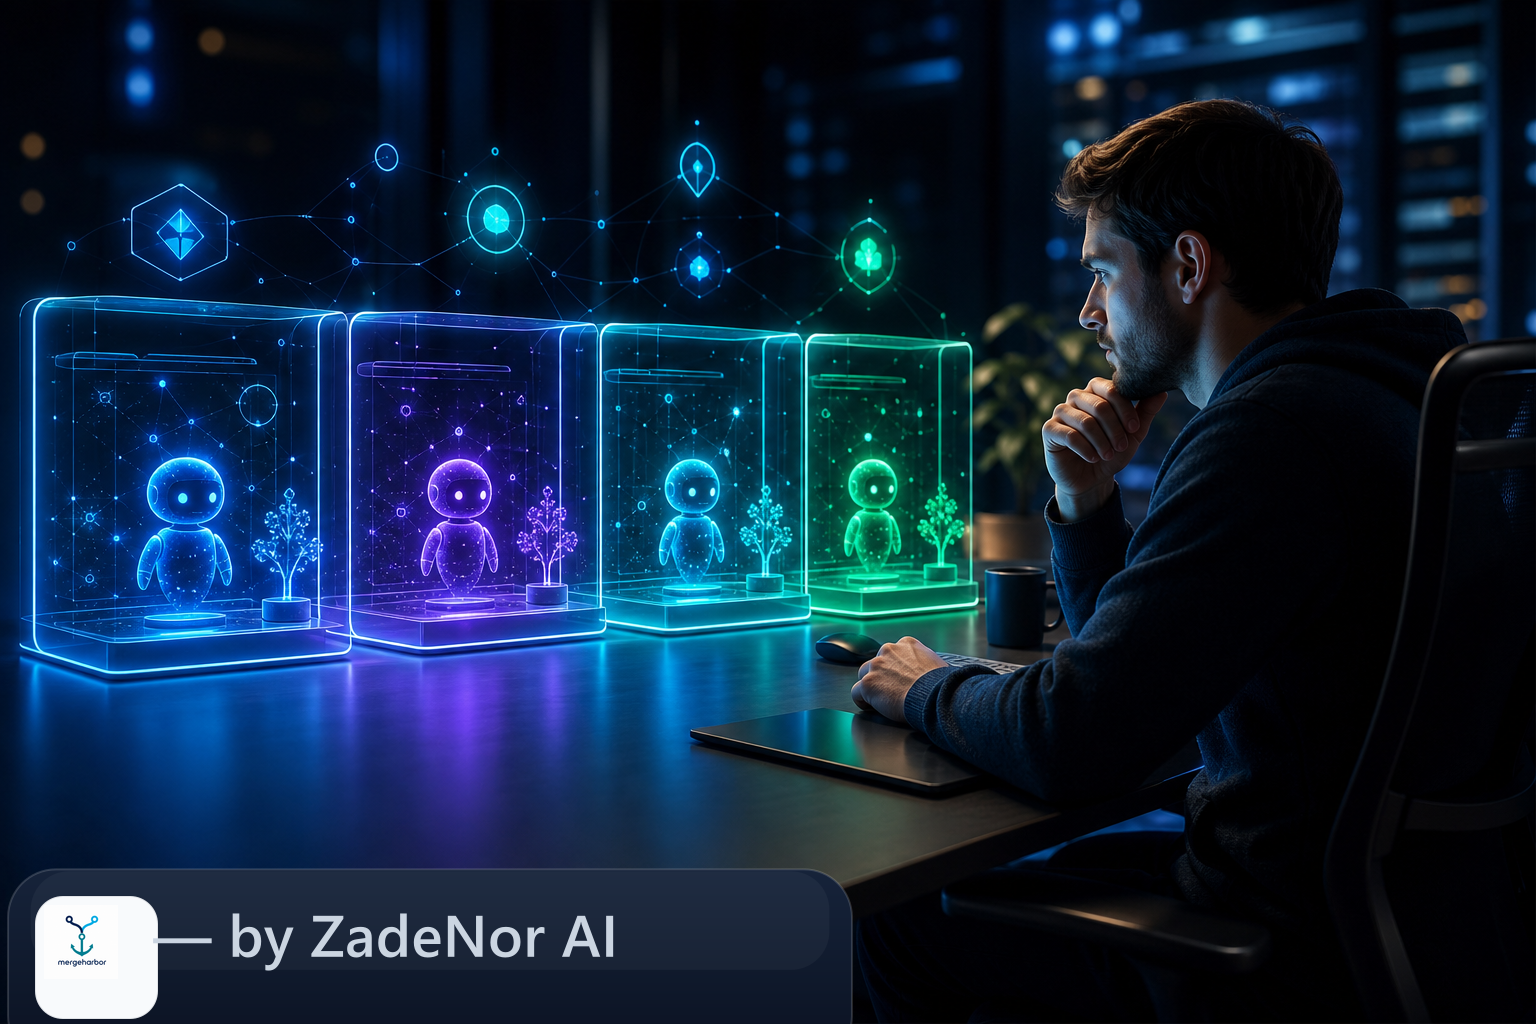
This is where MergeHarbor comes in — the open-source AI coding agent orchestrator built by ZadeNor AI. Rather than one agent in one shared tree, MergeHarbor runs many agents in parallel, each isolated in its own git worktree. MergeHarbor tackles this with Overlap-aware task planning: MergeHarbor flags when two tasks target the same files, so you can serialize or re-scope them before they ever collide. MergeHarbor connects parallel orchestration, full runtime isolation, early conflict detection and safe serialized merges, so the whole workflow moves as one.
The Evidence
The principle is simple: fan work out across many agents, keep every task isolated, and merge it back in safely. It works because the whole workflow runs on standard git worktrees — every task tracked, isolated, and merged back through one safe path. The pattern holds across ml engineering teams of every size: when each agent is isolated and merges are serialized, parallel AI-assisted work becomes safe. This is not about removing the developer; it is about giving you a control plane and agents that can never step on each other.
The Result
The numbers follow the rigour: more work shipped in parallel, fewer late conflicts, and a main branch you can trust. Teams using this approach see Higher throughput from parallel execution during sustained growth. For ml engineering teams, that means higher throughput from parallel execution you can actually rely on.
Get Started
Want higher throughput from parallel execution during sustained growth as a ML Engineering Teams? Explore MergeHarbor by ZadeNor AI and see how isolated worktrees and safe serialized merges keep parallel agents fast and conflict-free. Free and open source.
Every minute lost to no way to queue, prioritize and sequence agent tasks as the team scales is a minute not spent on the change that actually matters. For leaders, the real risk is strategic: coordination drag becomes a ceiling on how much AI-assisted work the team can take on. The cost of no way to queue, prioritize and sequence agent tasks as the team scales is rarely a single number — it is stalled work, late conflicts, and avoidable rework. For ml engineering teams, that means higher throughput from parallel execution you can actually rely on. Coordination stops being a daily scramble and starts being a competitive advantage. You get a calm, orchestrated flow; your throughput goes up and your merges stay clean.
What looks like a tooling problem is often an isolation and merge problem in disguise. The cost of no way to queue, prioritize and sequence agent tasks as the team scales is rarely a single number — it is stalled work, late conflicts, and avoidable rework. Teams end up serializing everything by hand instead of running agents in parallel with confidence. Teams using this approach see Higher throughput from parallel execution during sustained growth. The numbers follow the rigour: more work shipped in parallel, fewer late conflicts, and a main branch you can trust.
Teams end up serializing everything by hand instead of running agents in parallel with confidence. Over time, no way to queue, prioritize and sequence agent tasks as the team scales translates into slower cycles, hidden regressions, and throughput no one wants to give away. Coordination stops being a daily scramble and starts being a competitive advantage. For ml engineering teams, that means higher throughput from parallel execution you can actually rely on. The numbers follow the rigour: more work shipped in parallel, fewer late conflicts, and a main branch you can trust.
Teams end up serializing everything by hand instead of running agents in parallel with confidence. Every minute lost to no way to queue, prioritize and sequence agent tasks as the team scales is a minute not spent on the change that actually matters. For leaders, the real risk is strategic: coordination drag becomes a ceiling on how much AI-assisted work the team can take on. Coordination stops being a daily scramble and starts being a competitive advantage. Teams using this approach see Higher throughput from parallel execution during sustained growth. You get a calm, orchestrated flow; your throughput goes up and your merges stay clean.