Overview
Most questions about the numbers are simple; getting them answered rarely is. Every team has data in spreadsheets and exports — the hard part is turning it into answers without waiting on an analyst. The way a team works with its data says a lot about how quickly it can act. For media & entertainment, the difference between a fast decision and a stalled one often comes down to how quickly a simple question about the data gets a trustworthy answer.
The Problem
For a Operations Manager, waiting on a data pipeline before anyone can look in read-from-url data feeds is more than an inconvenience — it is a daily drag on how fast the team can move. When waiting on a data pipeline before anyone can look in read-from-url data feeds sets in, decisions slow down and the data team drowns in ad-hoc requests. A recurring challenge for media & entertainment is waiting on a data pipeline before anyone can look in read-from-url data feeds. It rarely starts as a crisis; waiting on a data pipeline before anyone can look in read-from-url data feeds builds quietly until a board deadline makes it impossible to ignore. Left unaddressed, waiting on a data pipeline before anyone can look in read-from-url data feeds compounds: questions pile up, reports go stale, and insight stays locked away.
Common Questions
Can the whole team use it? Yes — that is the point. Business users answer their own questions in plain language, clearing the ad-hoc backlog and freeing the data team for deeper work.
Do I need to know SQL? No. TalkLytx writes the SQL from your question — and shows it to you, editable, so you can verify or refine the logic if you want to.
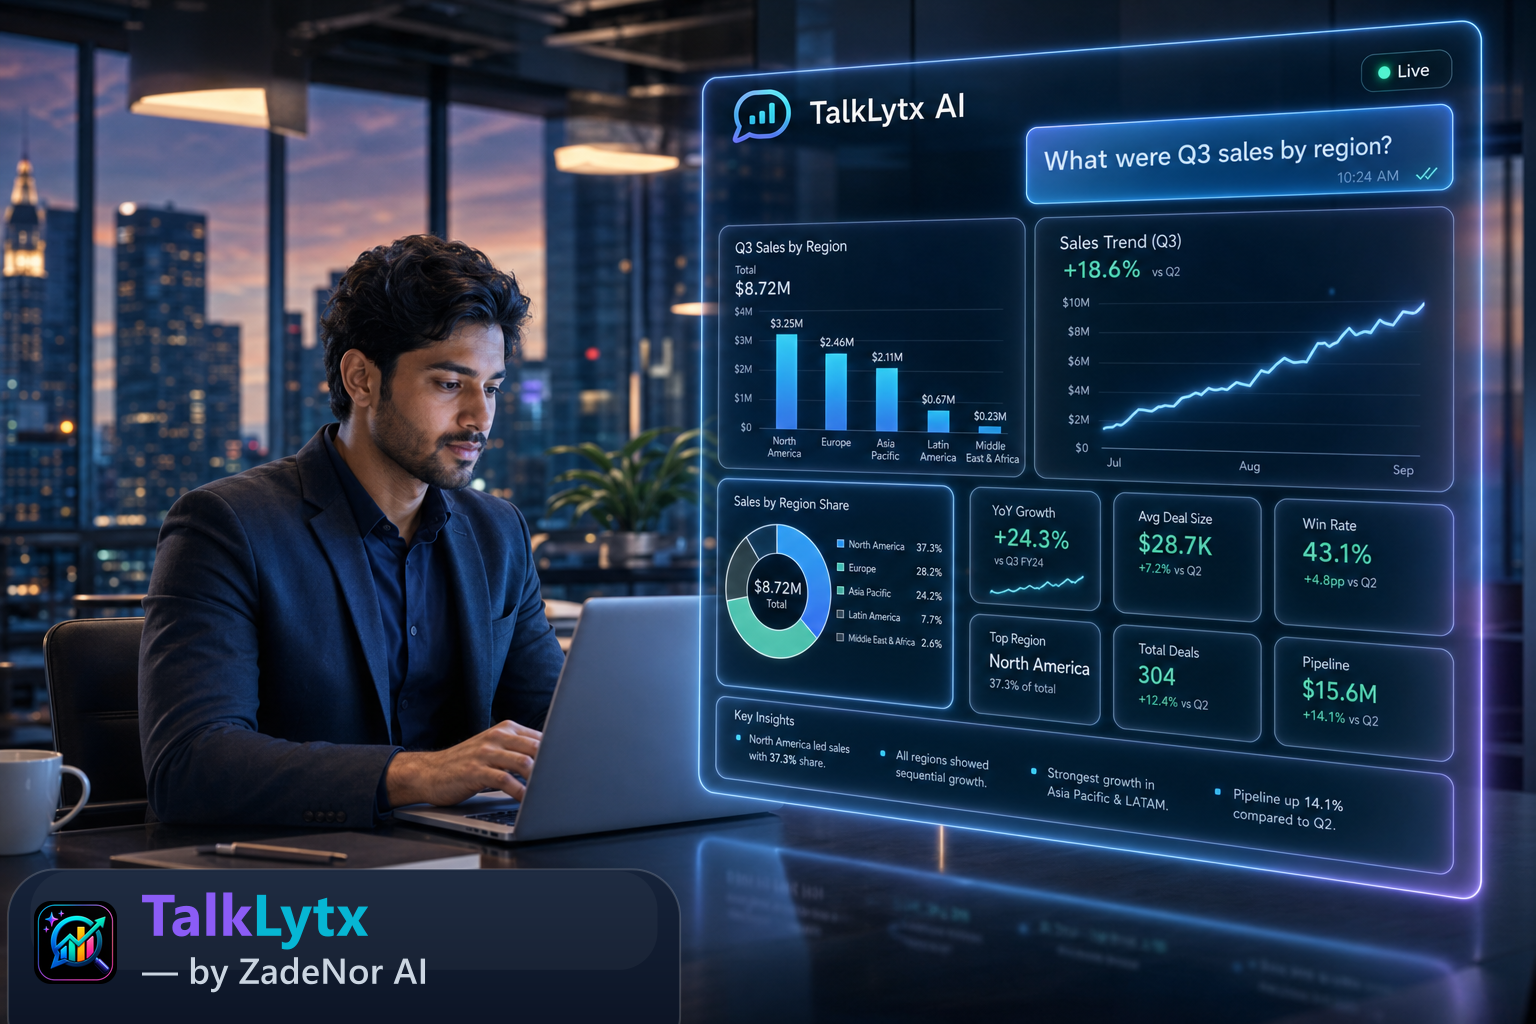
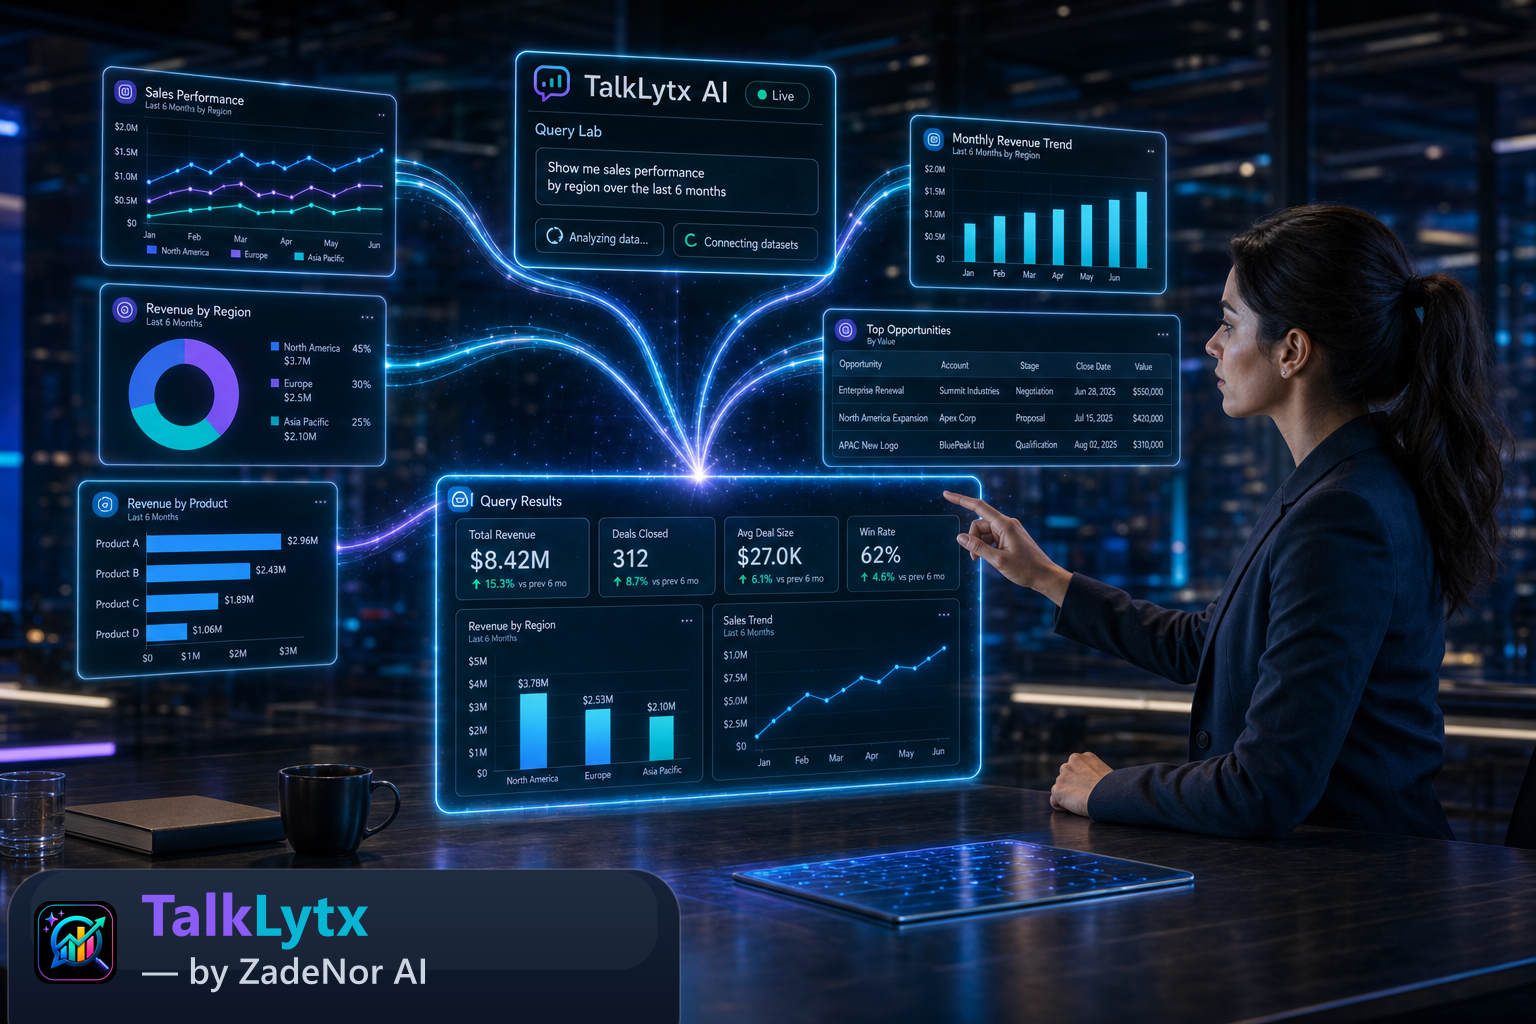
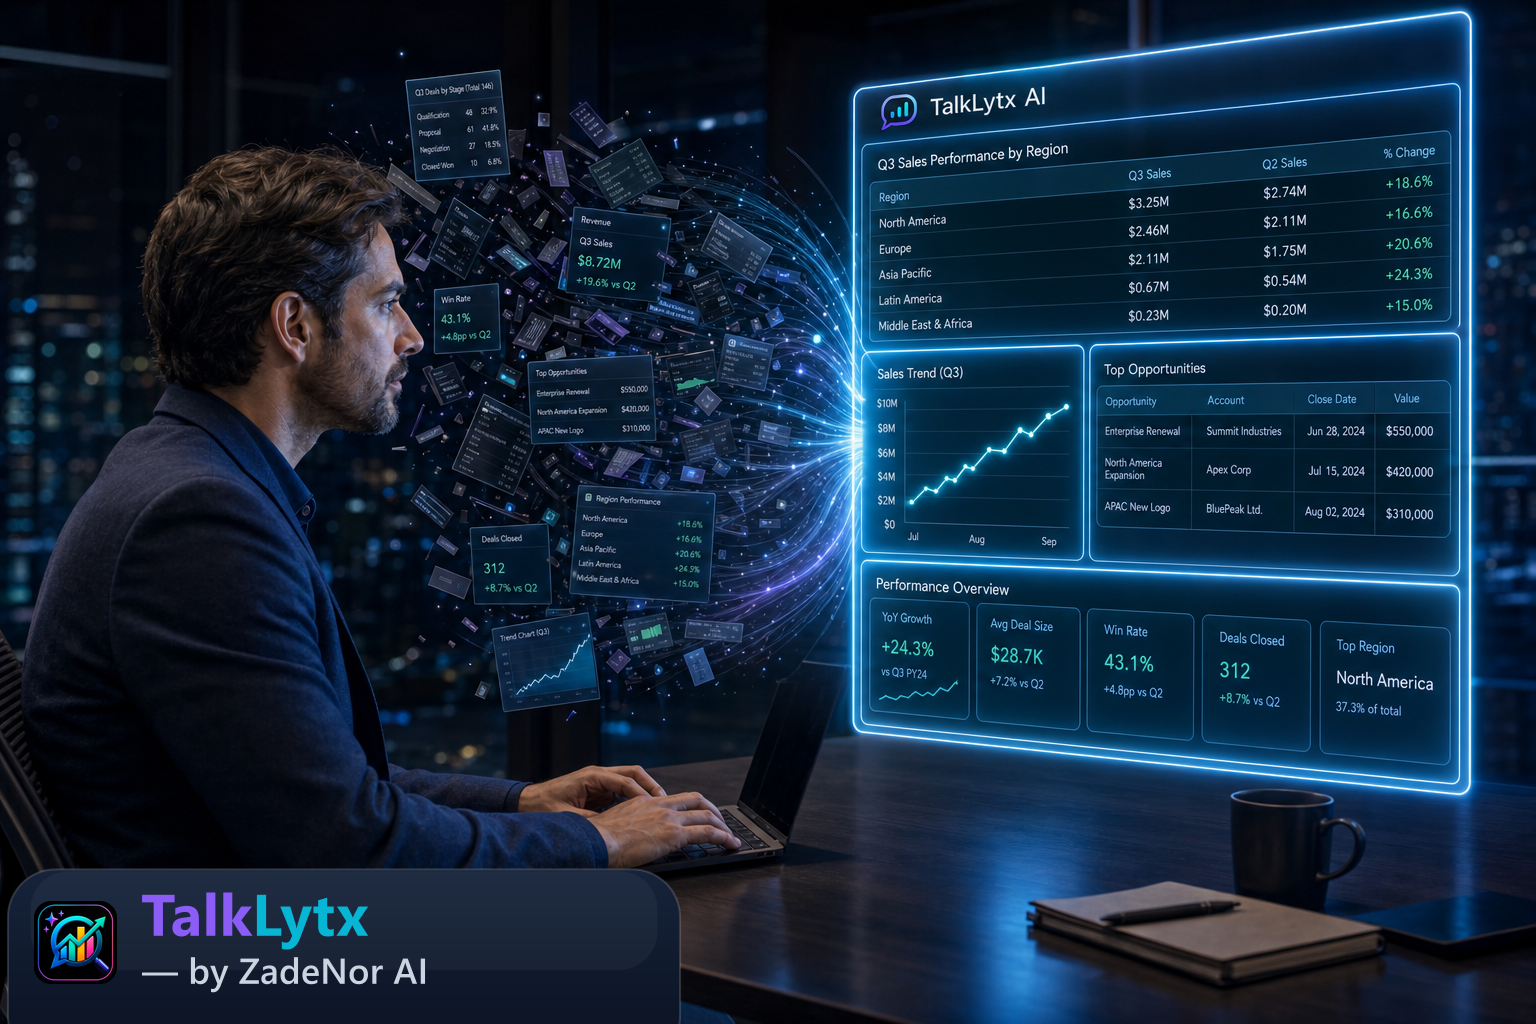
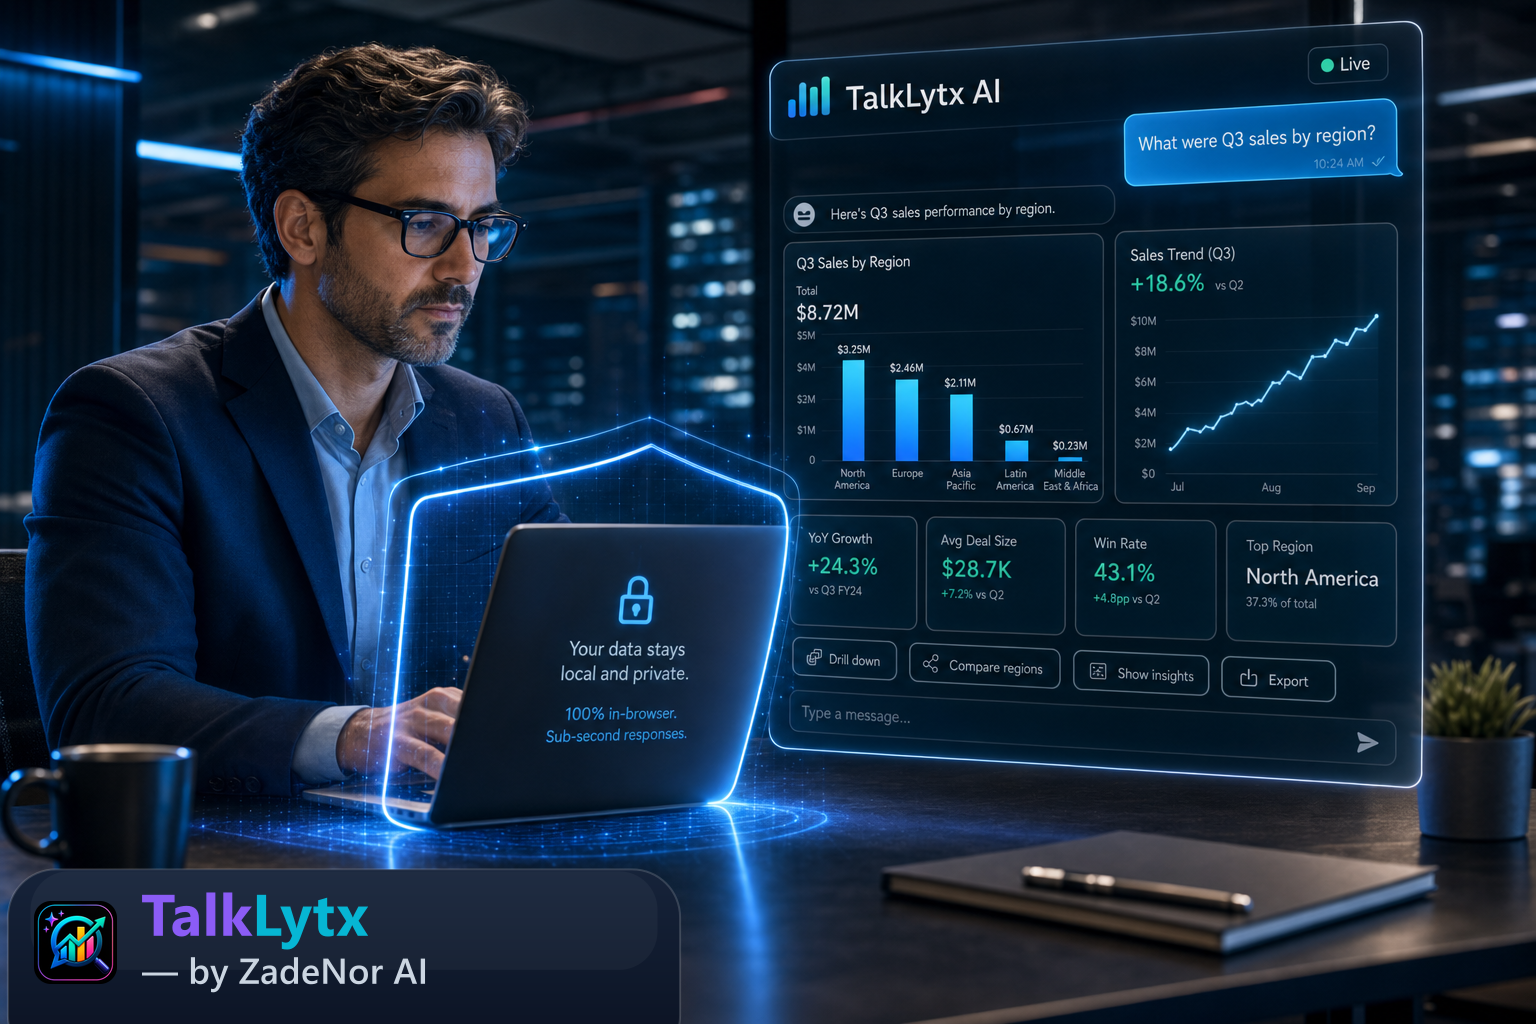
Is TalkLytx just another BI tool? No — it is a conversational data-analytics platform: upload CSV, JSON, Excel or PDF (or read from a URL), ask in plain English, and get AI-generated SQL, instant charts and pinned dashboards, all in one workspace.
Where does my data go? Analysis can run in an in-browser DuckDB-Wasm engine for privacy and speed, so URL-based data stays on your machine instead of being shipped to a heavyweight warehouse.
The TalkLytx Approach
Since read-from-URL data feeds sits within the Platform capability set, it fits naturally into how media & entertainment already work. Because the answer, the SQL and the chart arrive together, you work from one transparent source of truth instead of a black box. TalkLytx connects natural-language questions, AI-generated SQL, and instant charts, so the whole analysis moves like a conversation. This is where TalkLytx comes in — the conversational data-analytics platform built by ZadeNor AI.
What You Gain
People using this approach see No more waiting on the BI queue across customer segments. Analytics stops being a bottleneck and starts being a shared, everyday capability. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. The result is no more waiting on the bi queue, without adding headcount or waiting on the queue. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see.
Explore TalkLytx
Give every team its own analytics. Try TalkLytx — by ZadeNor AI — and watch questions, SQL, charts and dashboards come together in one edge-native workspace. Start free in minutes.
Teams end up waiting on the BI queue instead of exploring the data themselves. Every hour lost to waiting on a data pipeline before anyone can look in read-from-url data feeds is an hour not spent on the decision the numbers were meant to inform. Over time, waiting on a data pipeline before anyone can look in read-from-url data feeds translates into slower reporting, duplicated work, and insight that never reaches the people who need it. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. People using this approach see No more waiting on the BI queue across customer segments.
What looks like a tooling problem is often an access and trust problem in disguise. Teams end up waiting on the BI queue instead of exploring the data themselves. For media & entertainment, that means no more waiting on the bi queue you can actually rely on. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions.
For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. What looks like a tooling problem is often an access and trust problem in disguise. Teams end up waiting on the BI queue instead of exploring the data themselves. People using this approach see No more waiting on the BI queue across customer segments. The result is no more waiting on the bi queue, without adding headcount or waiting on the queue. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see.
Teams end up waiting on the BI queue instead of exploring the data themselves. For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. Over time, waiting on a data pipeline before anyone can look in read-from-url data feeds translates into slower reporting, duplicated work, and insight that never reaches the people who need it. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. Analytics stops being a bottleneck and starts being a shared, everyday capability. The result is no more waiting on the bi queue, without adding headcount or waiting on the queue.