The Scenario
AI coding agents are powerful, but running more than one at a time usually means chaos in a single shared working tree. For site reliability engineers, the difference between shipping calmly and firefighting often comes down to how many agents you can run at once and how safely you can merge their work. Expectations for developer velocity have shifted, and the tools people rely on have to keep up. Most site reliability engineers know the feeling: one agent runs, everyone else waits, and merges turn into a scramble.
The Problem
It rarely starts as a crisis; conflicts that surface only at the final merge builds quietly until a big merge makes it impossible to ignore. For a Senior Infrastructure, conflicts that surface only at the final merge is more than an inconvenience — it is a daily drag on velocity and peace of mind. A recurring challenge for site reliability engineers is conflicts that surface only at the final merge. When conflicts that surface only at the final merge sets in, the day tightens and the risk of a broken build or lost work grows.
How MergeHarbor Handles It
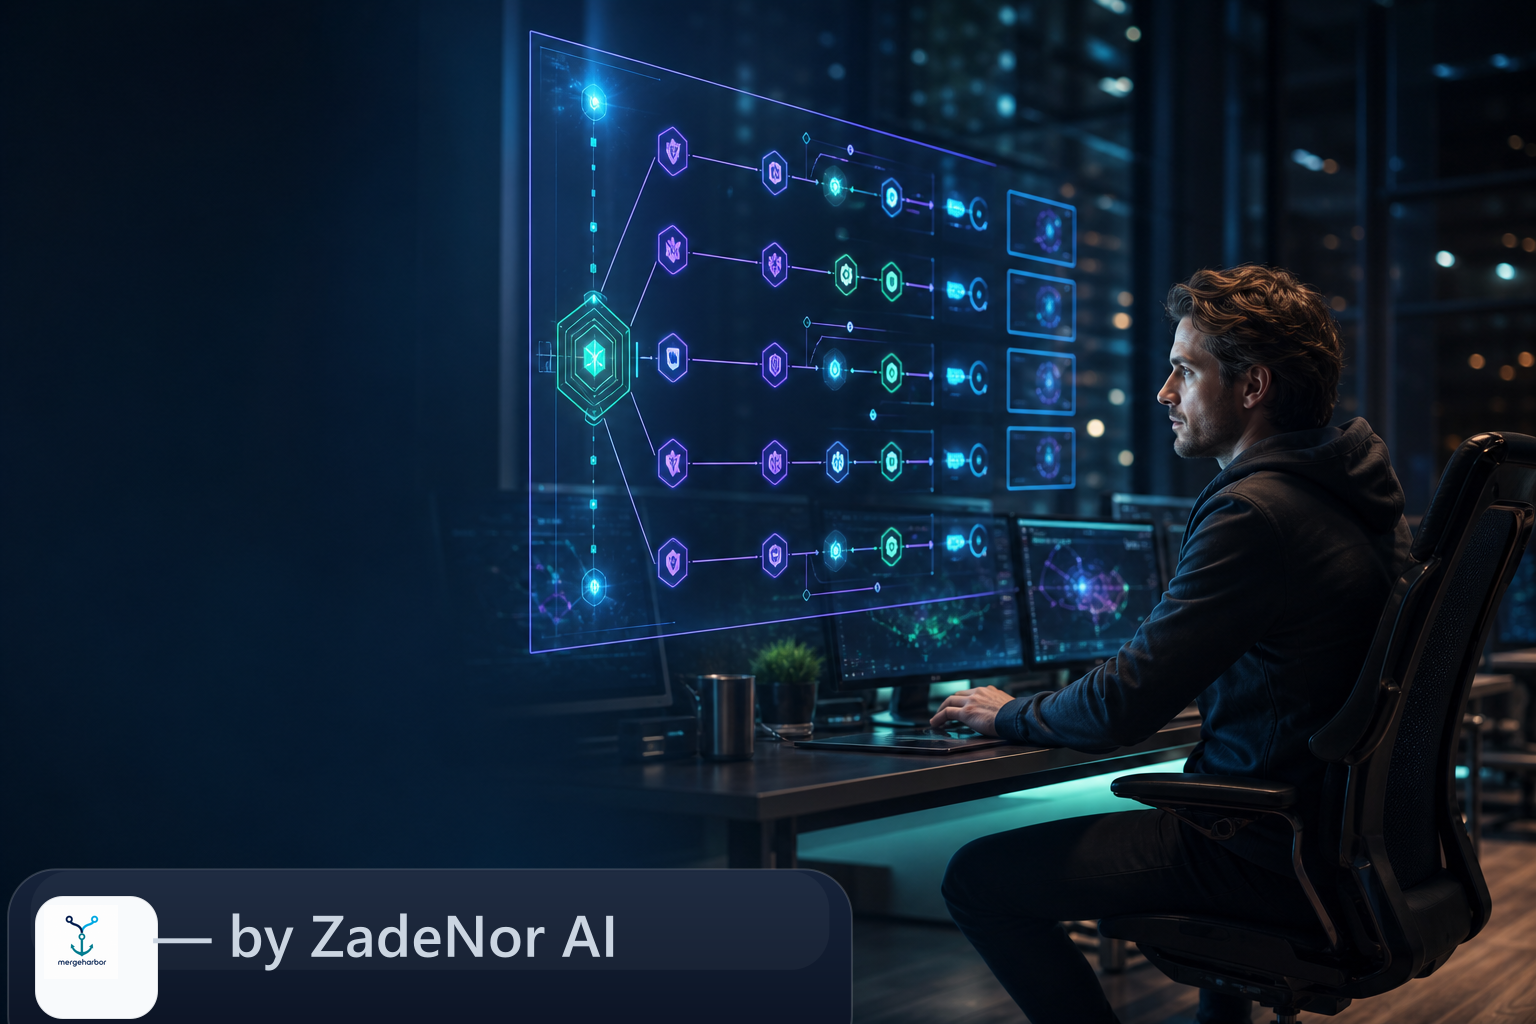
Because every task is isolated and merged back safely, you work from a clean, coordinated flow instead of a tangled working directory. Rather than one agent in one shared tree, MergeHarbor runs many agents in parallel, each isolated in its own git worktree. MergeHarbor connects parallel orchestration, full runtime isolation, early conflict detection and safe serialized merges, so the whole workflow moves as one.
How It Works
Every run is logged with its task and diff, and completed work is easy to review across worktrees before anything lands. Getting started is straightforward: point MergeHarbor at your repo and it spins up an isolated git worktree per task, so agents never share a working tree. When tasks complete, a safe, serialized merge queue lands them one at a time, rechecking for conflicts so the main branch stays green. Each agent runs in full runtime isolation with its own dependencies and build state, so one task can never corrupt another. You can drive the whole fleet from the CLI (mergeharbor, or mh), or let any MCP-compatible AI tool orchestrate it through the built-in MCP server.
The Outcome
The numbers follow the rigour: more work shipped in parallel, fewer late conflicts, and a main branch you can trust. The result is many ai agents working in parallel, safely at scale, without trading away isolation or safety. Coordination stops being a daily scramble and starts being a competitive advantage.
Try It Yourself
Give your team one control plane for parallel AI coding agents. Try MergeHarbor — by ZadeNor AI — and watch orchestration, isolation and safe merging work together. Clone the open-source repo in minutes.
Every minute lost to conflicts that surface only at the final merge is a minute not spent on the change that actually matters. The cost of conflicts that surface only at the final merge is rarely a single number — it is stalled work, late conflicts, and avoidable rework. The result is many ai agents working in parallel, safely at scale, without trading away isolation or safety. You get a calm, orchestrated flow; your throughput goes up and your merges stay clean. The numbers follow the rigour: more work shipped in parallel, fewer late conflicts, and a main branch you can trust.
For leaders, the real risk is strategic: coordination drag becomes a ceiling on how much AI-assisted work the team can take on. Over time, conflicts that surface only at the final merge translates into slower cycles, hidden regressions, and throughput no one wants to give away. The result is many ai agents working in parallel, safely at scale, without trading away isolation or safety. Coordination stops being a daily scramble and starts being a competitive advantage. The numbers follow the rigour: more work shipped in parallel, fewer late conflicts, and a main branch you can trust.
Teams end up serializing everything by hand instead of running agents in parallel with confidence. Every minute lost to conflicts that surface only at the final merge is a minute not spent on the change that actually matters. Teams using this approach see Many AI agents working in parallel, safely at scale. For site reliability engineers, that means many ai agents working in parallel, safely at scale you can actually rely on. You get a calm, orchestrated flow; your throughput goes up and your merges stay clean.
For leaders, the real risk is strategic: coordination drag becomes a ceiling on how much AI-assisted work the team can take on. What looks like a tooling problem is often an isolation and merge problem in disguise. Over time, conflicts that surface only at the final merge translates into slower cycles, hidden regressions, and throughput no one wants to give away. The result is many ai agents working in parallel, safely at scale, without trading away isolation or safety. Coordination stops being a daily scramble and starts being a competitive advantage.
Teams end up serializing everything by hand instead of running agents in parallel with confidence. The cost of conflicts that surface only at the final merge is rarely a single number — it is stalled work, late conflicts, and avoidable rework. The result is many ai agents working in parallel, safely at scale, without trading away isolation or safety. For site reliability engineers, that means many ai agents working in parallel, safely at scale you can actually rely on.