Overview
Most questions about the numbers are simple; getting them answered rarely is. The way a team works with its data says a lot about how quickly it can act. Most education & research know the feeling: the answer is somewhere in the files, but reaching it means a queue, a query, or a rebuild. Every team has data in spreadsheets and exports — the hard part is turning it into answers without waiting on an analyst.
Why This Matters
When files too big or too varied sets in, decisions slow down and the data team drowns in ad-hoc requests. The issue shows up most clearly as Files too big or too varied for a spreadsheet to handle in fast-moving markets. Left unaddressed, files too big or too varied compounds: questions pile up, reports go stale, and insight stays locked away. A recurring challenge for education & research is files too big or too varied.
The Method
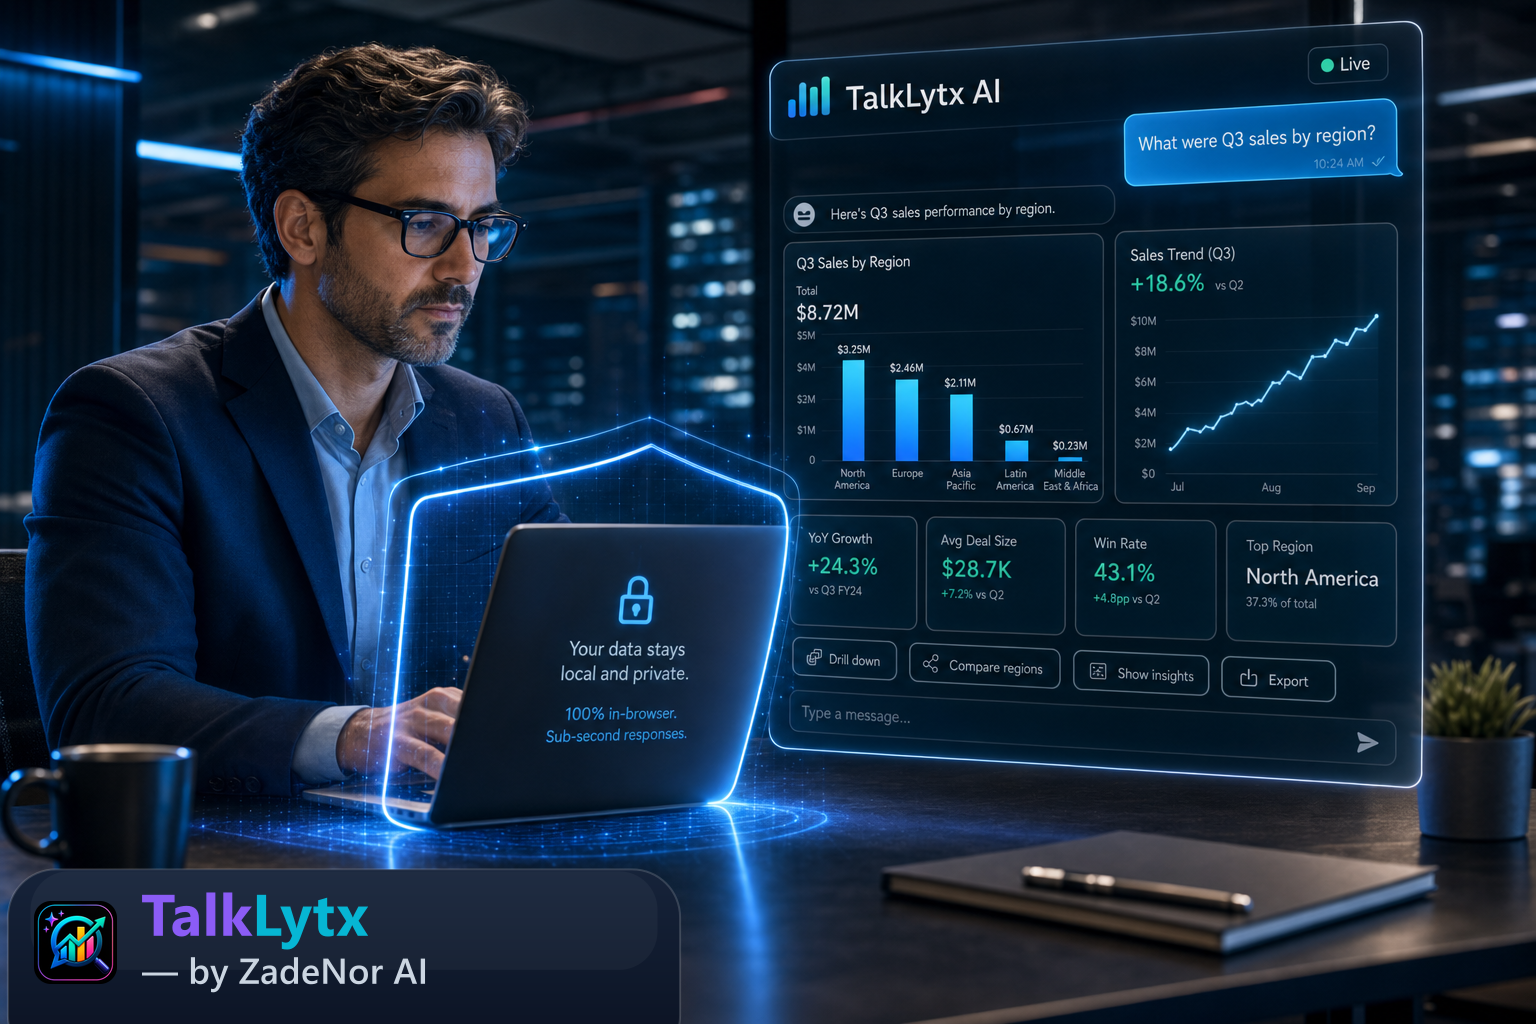
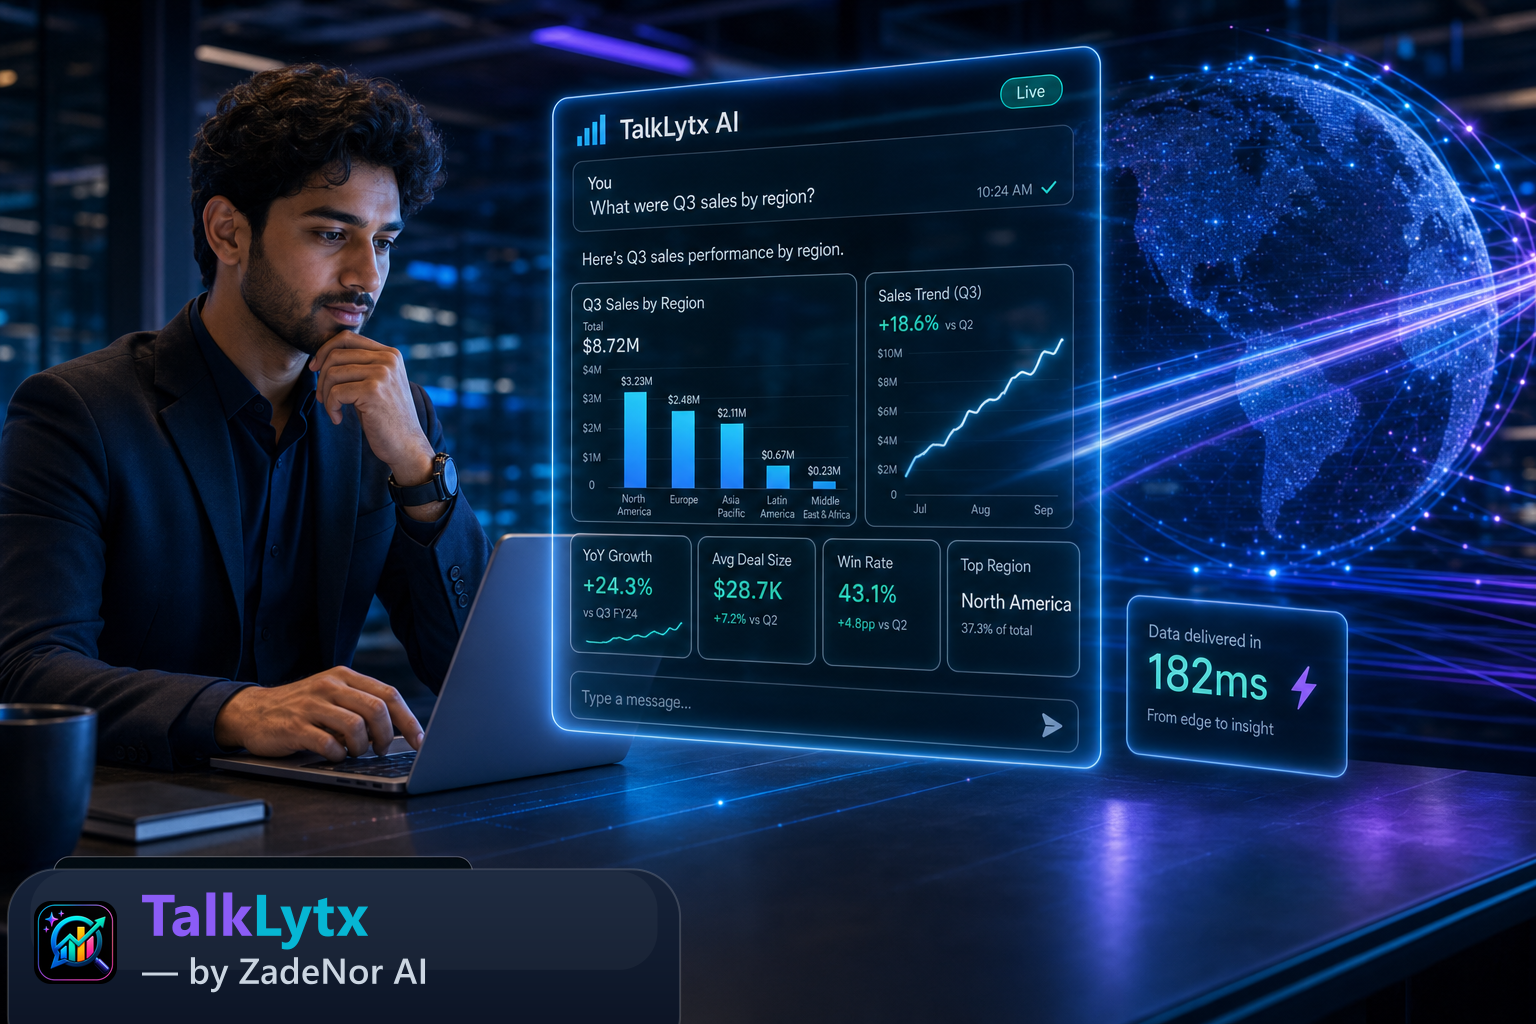
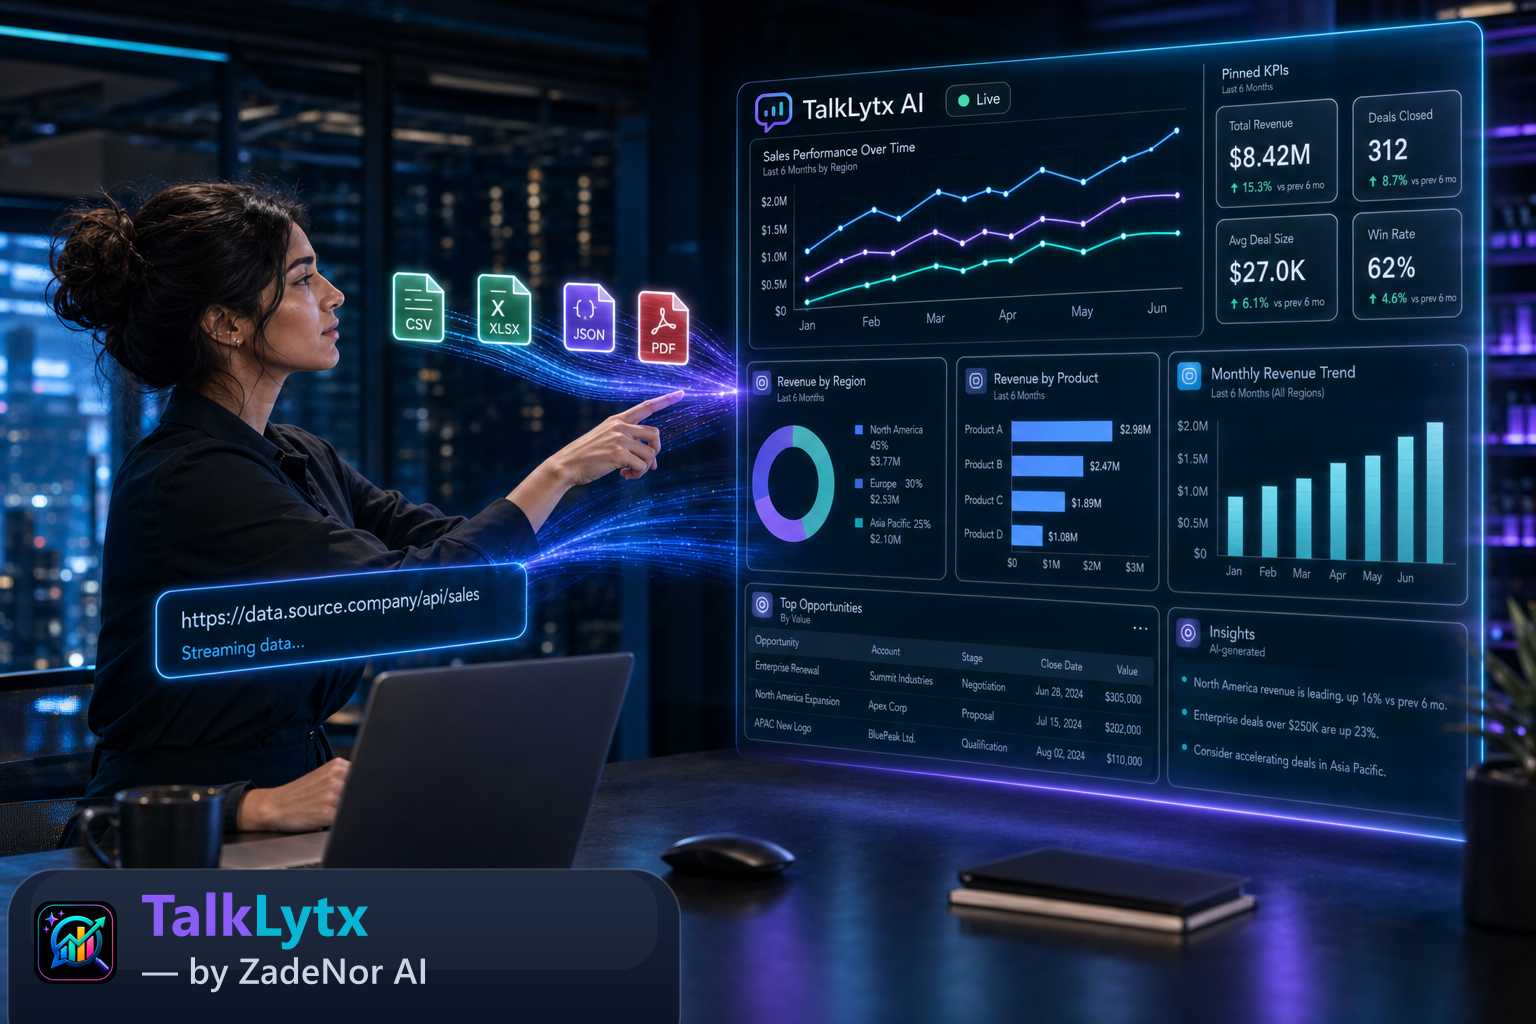
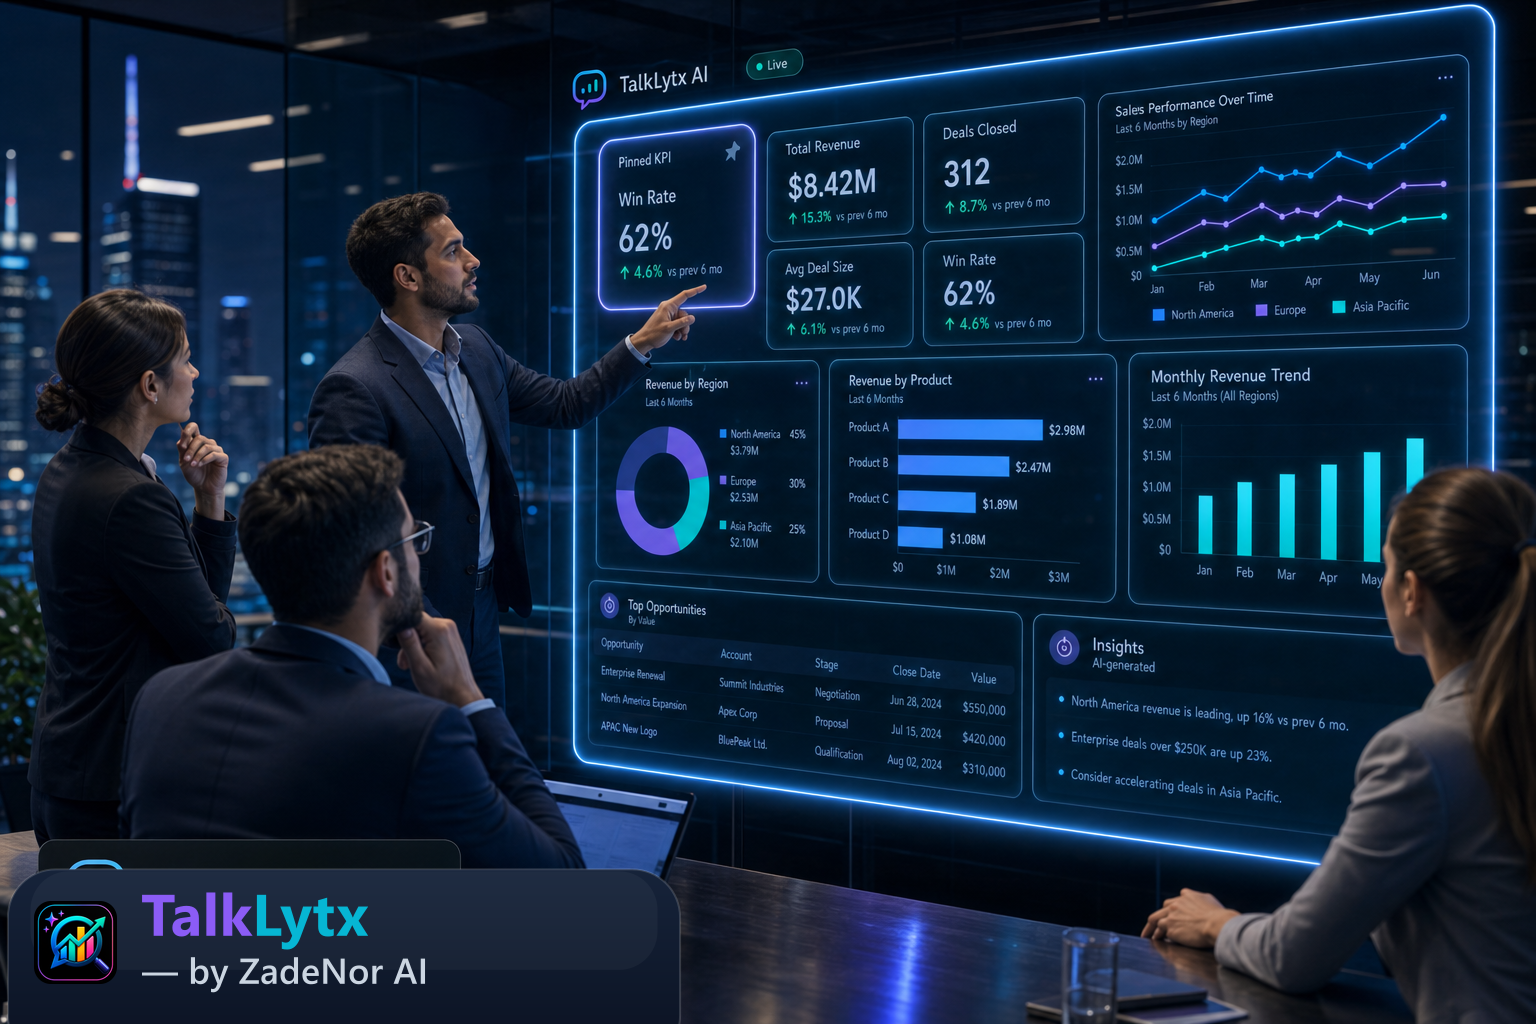
Ask a question in plain English and TalkLytx writes the SQL, runs it, and answers with a written explanation and a chart. Getting started is straightforward: drag in a CSV, JSON, Excel or PDF — or point TalkLytx at a URL — and start asking questions in seconds. Follow-up questions keep their context, so refining an answer feels like a conversation rather than a rewrite. Pin any chart or KPI to a dashboard your whole team can open and ask their own follow-ups on.
How TalkLytx Helps
TalkLytx tackles this with Cross-dataset joins: Combine data from several files or sources in one query, ending the manual copy-paste between spreadsheets. Rather than another BI tool to learn, TalkLytx lets you upload a file or read from a URL and simply ask your question in plain English. Since cross-dataset joins sits within the Query Lab capability set, it fits naturally into how education & research already work. TalkLytx connects natural-language questions, AI-generated SQL, and instant charts, so the whole analysis moves like a conversation.
What Good Looks Like
People using this approach see Clean, joined data without the busywork without adding data headcount. The result is clean, joined data without the busywork without adding data headcount, without adding headcount or waiting on the queue. Analytics stops being a bottleneck and starts being a shared, everyday capability. For education & research, that means clean, joined data without the busywork without adding data headcount you can actually rely on. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions.
Explore TalkLytx
Give every team its own analytics. Try TalkLytx — by ZadeNor AI — and watch questions, SQL, charts and dashboards come together in one edge-native workspace. Start free in minutes.
What looks like a tooling problem is often an access and trust problem in disguise. Teams end up waiting on the BI queue instead of exploring the data themselves. The cost of files too big or too varied is rarely a single number — it is decisions made late, on stale data, or on gut feel. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. The result is clean, joined data without the busywork without adding data headcount, without adding headcount or waiting on the queue. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see.
For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. Teams end up waiting on the BI queue instead of exploring the data themselves. The result is clean, joined data without the busywork without adding data headcount, without adding headcount or waiting on the queue. For education & research, that means clean, joined data without the busywork without adding data headcount you can actually rely on. Analytics stops being a bottleneck and starts being a shared, everyday capability.
For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. The cost of files too big or too varied is rarely a single number — it is decisions made late, on stale data, or on gut feel. Teams end up waiting on the BI queue instead of exploring the data themselves. People using this approach see Clean, joined data without the busywork without adding data headcount. The result is clean, joined data without the busywork without adding data headcount, without adding headcount or waiting on the queue. Analytics stops being a bottleneck and starts being a shared, everyday capability.
Over time, files too big or too varied translates into slower reporting, duplicated work, and insight that never reaches the people who need it. For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. The result is clean, joined data without the busywork without adding data headcount, without adding headcount or waiting on the queue. Analytics stops being a bottleneck and starts being a shared, everyday capability. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see.