Where Things Stand
Across Finance, the bar for speed, self-service and trust in the numbers keeps rising. Data grows at its own relentless pace, and a single slow reporting cycle can ripple across the whole business. In analytics, teams are compared not just to peers but to the fastest, most intuitive tools anyone has ever used.
The New Baseline
The modern standard is simple: upload or connect, ask, and get an answer in seconds. Self-serve analytics is the new default; people want to explore the data themselves, not file a request. Anything a tool cannot answer quickly, or explain transparently, now feels like a risk. People now expect to ask a question in plain English and get an answer, a chart and the SQL — without learning a query language.
Where It Breaks Down
When waiting on a data pipeline before anyone can look sets in, decisions slow down and the data team drowns in ad-hoc requests. A recurring challenge for fp&a & corporate finance is waiting on a data pipeline before anyone can look. The issue shows up most clearly as Waiting on a data pipeline before anyone can look for one-off deep dives. Left unaddressed, waiting on a data pipeline before anyone can look compounds: questions pile up, reports go stale, and insight stays locked away. For a Director of RevOps, waiting on a data pipeline before anyone can look is more than an inconvenience — it is a daily drag on how fast the team can move.
A New Operating Model
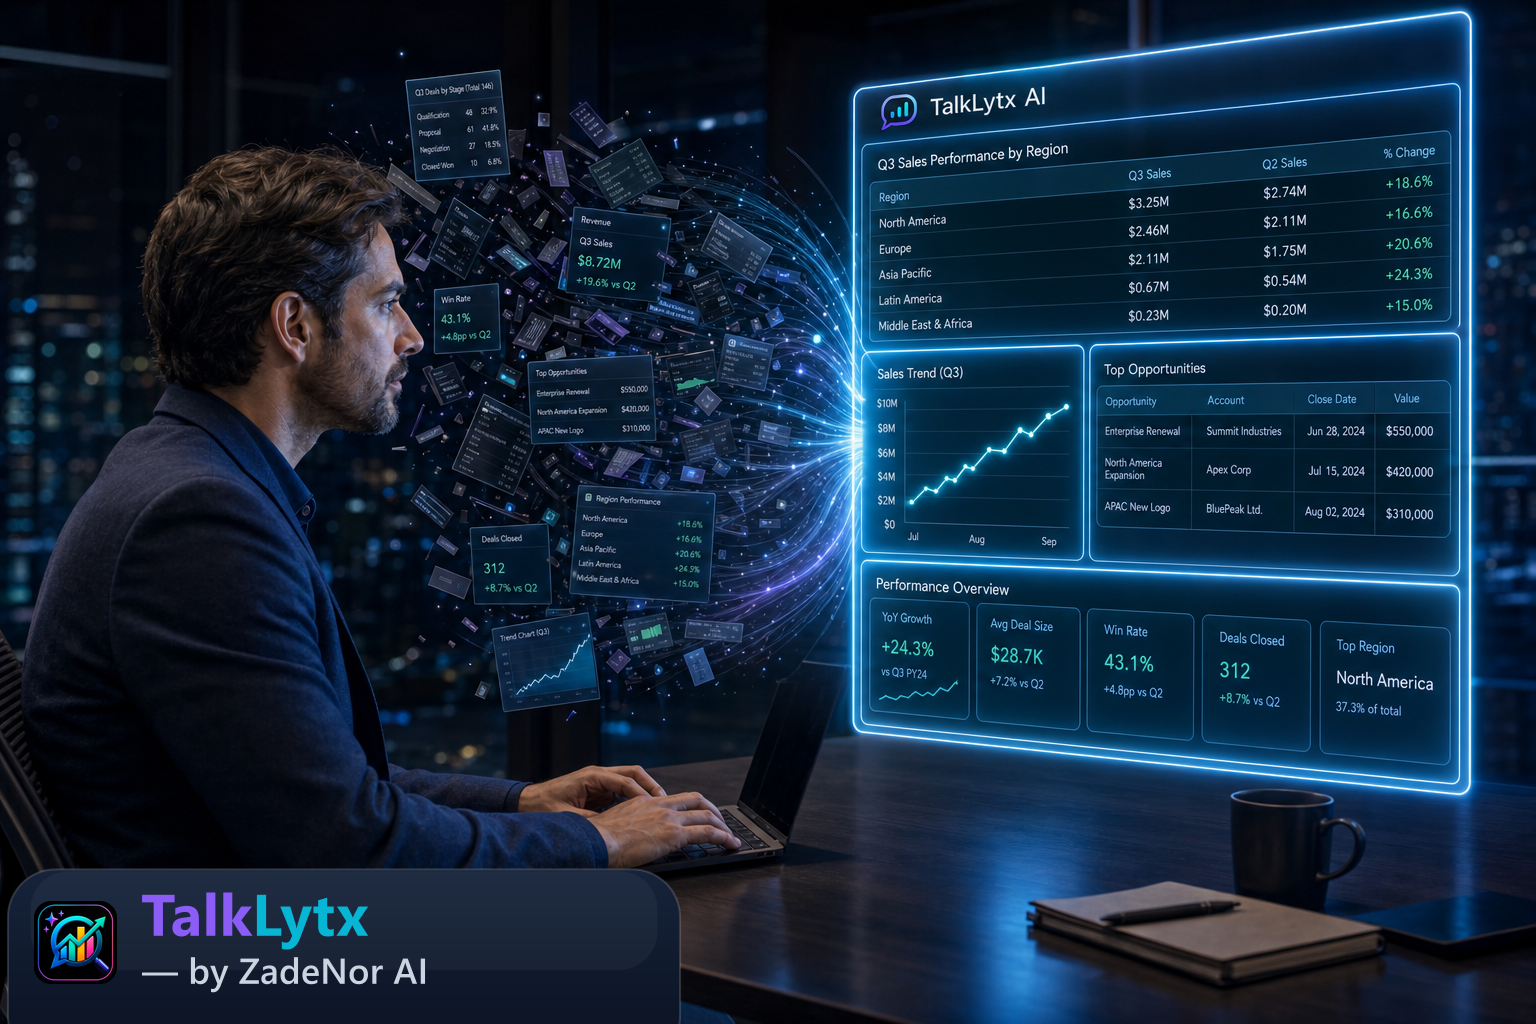
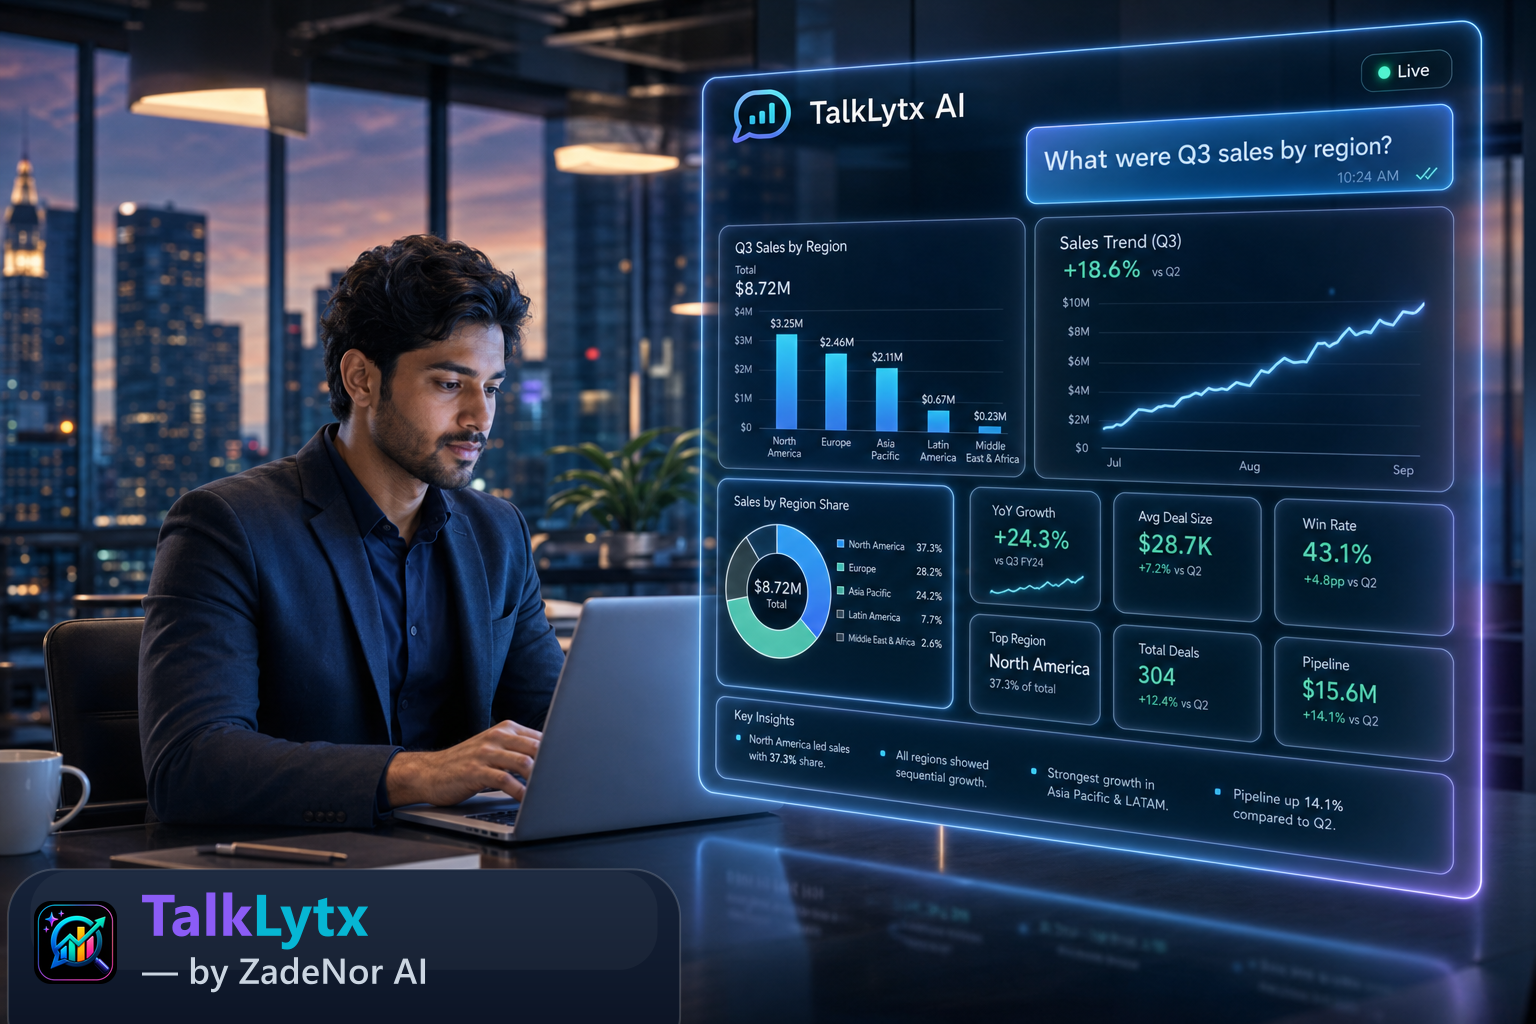
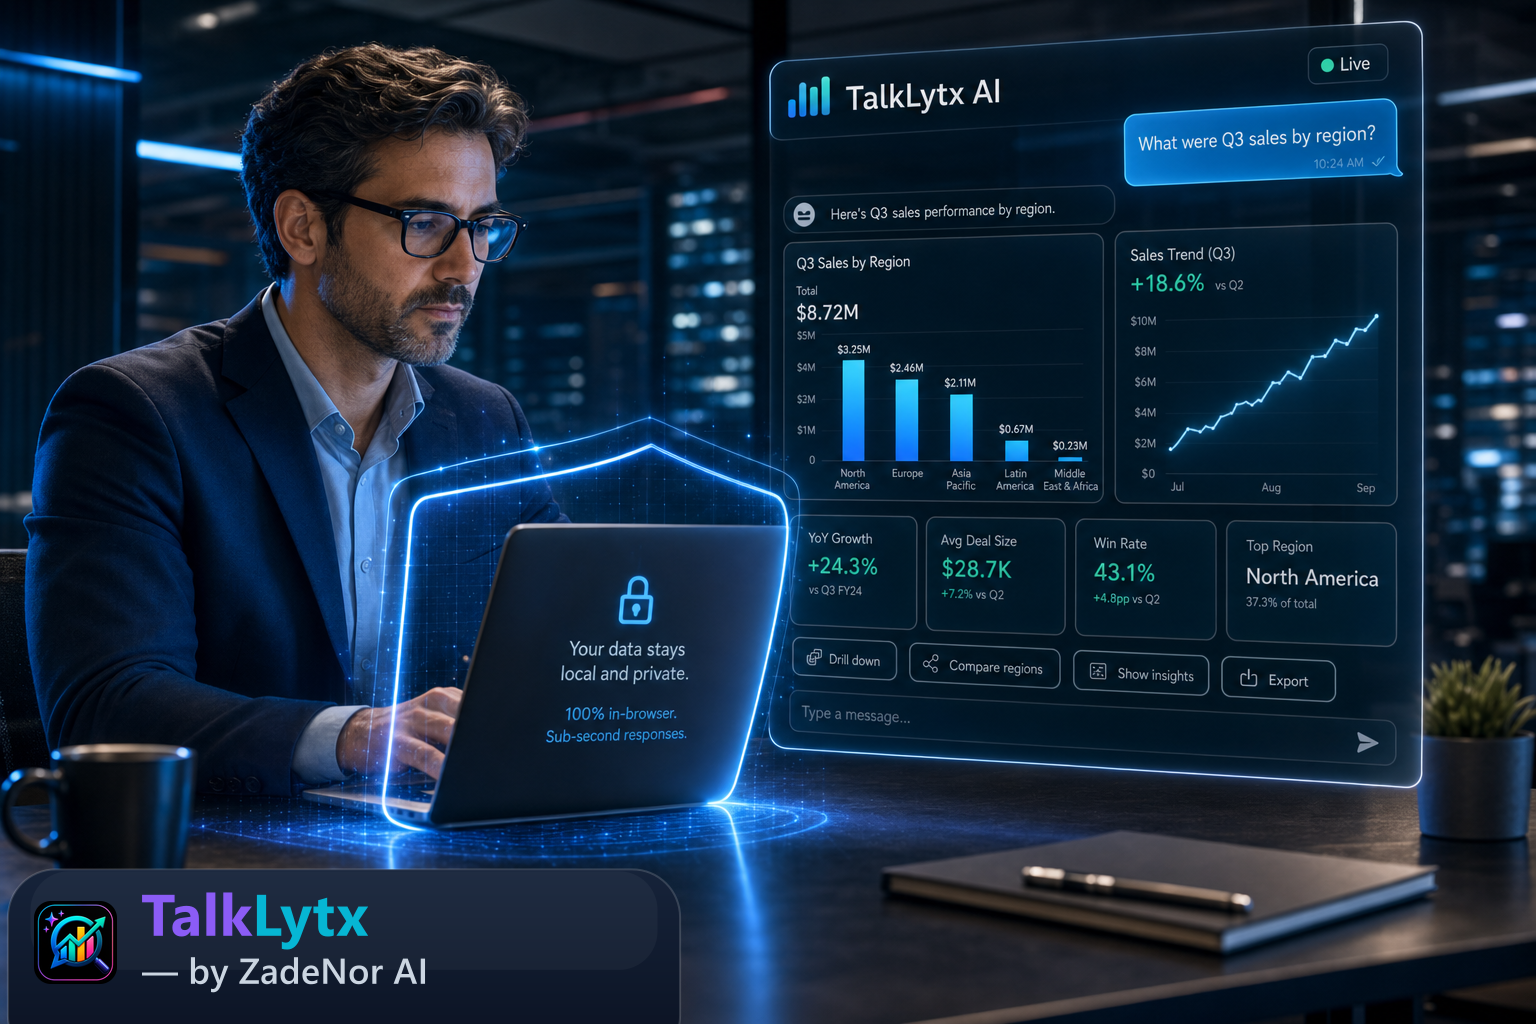
Since read-from-URL data feeds sits within the Platform capability set, it fits naturally into how fp&a & corporate finance already work. This is where TalkLytx comes in — the conversational data-analytics platform built by ZadeNor AI. TalkLytx connects natural-language questions, AI-generated SQL, and instant charts, so the whole analysis moves like a conversation. Because the answer, the SQL and the chart arrive together, you work from one transparent source of truth instead of a black box.
What Changes
Analytics stops being a bottleneck and starts being a shared, everyday capability. For fp&a & corporate finance, that means sub-second answers on the edge you can actually rely on. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. The result is sub-second answers on the edge, without adding headcount or waiting on the queue. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions.
Next Steps
See it for yourself: TalkLytx by ZadeNor AI writes the SQL, draws the chart, and shows you the logic behind every number. Start free today.
Teams end up waiting on the BI queue instead of exploring the data themselves. Over time, waiting on a data pipeline before anyone can look translates into slower reporting, duplicated work, and insight that never reaches the people who need it. For fp&a & corporate finance, that means sub-second answers on the edge you can actually rely on. The result is sub-second answers on the edge, without adding headcount or waiting on the queue.
Teams end up waiting on the BI queue instead of exploring the data themselves. Over time, waiting on a data pipeline before anyone can look translates into slower reporting, duplicated work, and insight that never reaches the people who need it. What looks like a tooling problem is often an access and trust problem in disguise. For fp&a & corporate finance, that means sub-second answers on the edge you can actually rely on. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. People using this approach see Sub-second answers on the edge for high-value decisions.
What looks like a tooling problem is often an access and trust problem in disguise. For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. People using this approach see Sub-second answers on the edge for high-value decisions. The result is sub-second answers on the edge, without adding headcount or waiting on the queue.
Every hour lost to waiting on a data pipeline before anyone can look is an hour not spent on the decision the numbers were meant to inform. Over time, waiting on a data pipeline before anyone can look translates into slower reporting, duplicated work, and insight that never reaches the people who need it. What looks like a tooling problem is often an access and trust problem in disguise. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions.
Every hour lost to waiting on a data pipeline before anyone can look is an hour not spent on the decision the numbers were meant to inform. Teams end up waiting on the BI queue instead of exploring the data themselves. Analytics stops being a bottleneck and starts being a shared, everyday capability. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. The result is sub-second answers on the edge, without adding headcount or waiting on the queue.