Up Close
The way a team works with its data says a lot about how quickly it can act. Most product & analytics teams know the feeling: the answer is somewhere in the files, but reaching it means a queue, a query, or a rebuild. Expectations around analytics have shifted, and the tools people rely on have to keep up.
The Gap
It rarely starts as a crisis; messy csvs that break before any analysis begins builds quietly until a board deadline makes it impossible to ignore. A recurring challenge for product & analytics teams is messy csvs that break before any analysis begins. For a Manager, Strategy, messy csvs that break before any analysis begins is more than an inconvenience — it is a daily drag on how fast the team can move.
How TalkLytx Delivers
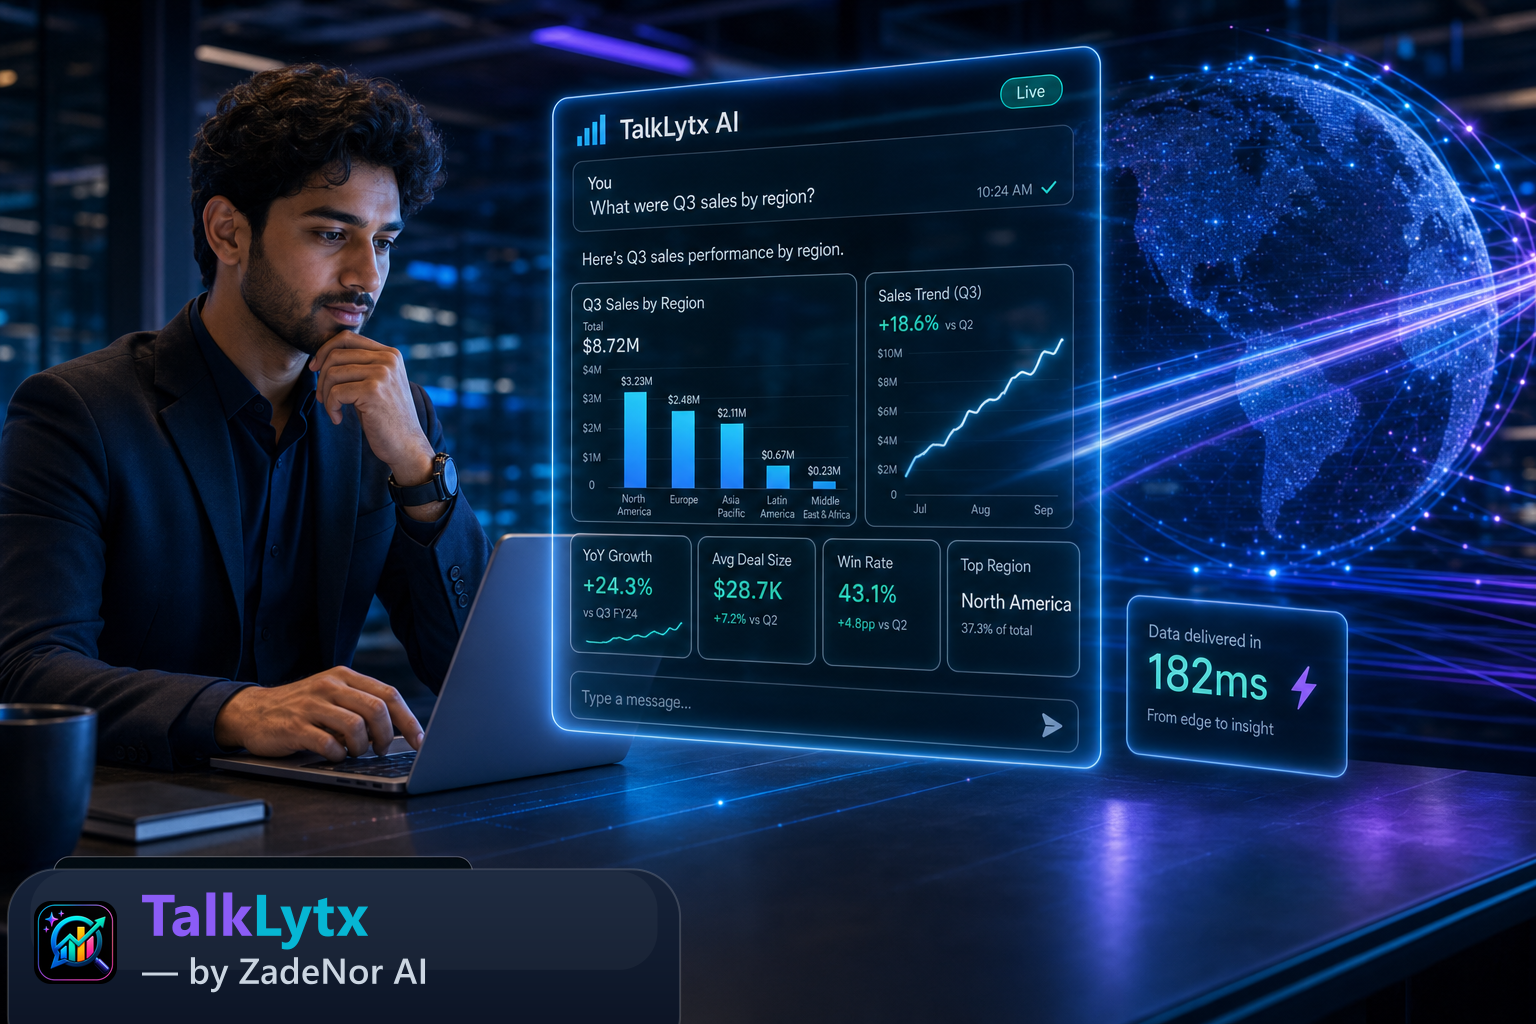
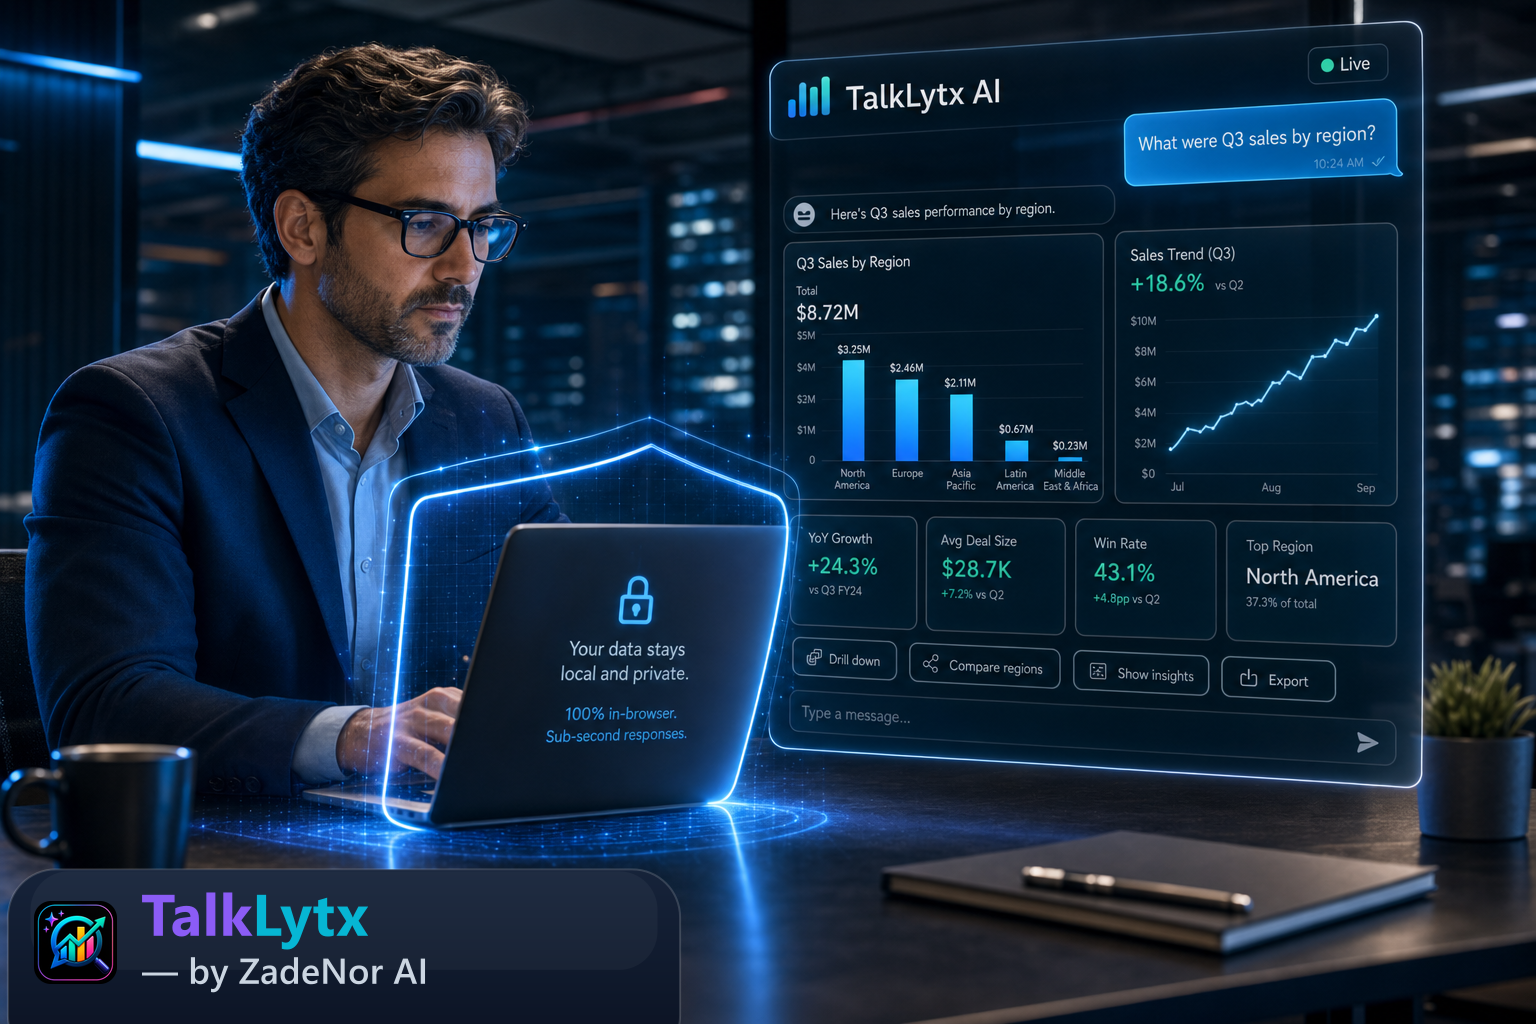
TalkLytx tackles this with Multi-dataset Query Lab: Write SQL across every connected dataset with JOINs, UNIONs, filters and aggregates, backed by a schema browser and click-to-insert templates. TalkLytx connects natural-language questions, AI-generated SQL, and instant charts, so the whole analysis moves like a conversation. Since multi-dataset Query Lab sits within the Query Lab capability set, it fits naturally into how product & analytics teams already work. Rather than another BI tool to learn, TalkLytx lets you upload a file or read from a URL and simply ask your question in plain English. This is where TalkLytx comes in — the conversational data-analytics platform built by ZadeNor AI.
Behind the Scenes
Ask a question in plain English and TalkLytx writes the SQL, runs it, and answers with a written explanation and a chart. Follow-up questions keep their context, so refining an answer feels like a conversation rather than a rewrite. The generated SQL is always visible and editable, so you can verify the logic behind any number instead of trusting a black box. Queries can run in an in-browser DuckDB-Wasm engine, so URL-based analysis stays private and answers come back in sub-second time. Getting started is straightforward: drag in a CSV, JSON, Excel or PDF — or point TalkLytx at a URL — and start asking questions in seconds.
Why It Matters
For product & analytics teams, that means charts and kpis pinned where the team can see them you can actually rely on. Analytics stops being a bottleneck and starts being a shared, everyday capability. The result is charts and kpis pinned where the team can see them, without adding headcount or waiting on the queue.
Take the Next Step
Make charts and kpis pinned where the team can see them for multi-source analysis the standard for how your team works with data. Get started with TalkLytx, the conversational analytics platform from ZadeNor AI — start free, no card required.
Every hour lost to messy csvs that break before any analysis begins is an hour not spent on the decision the numbers were meant to inform. Teams end up waiting on the BI queue instead of exploring the data themselves. The cost of messy csvs that break before any analysis begins is rarely a single number — it is decisions made late, on stale data, or on gut feel. People using this approach see Charts and KPIs pinned where the team can see them for multi-source analysis. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions.
For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. What looks like a tooling problem is often an access and trust problem in disguise. People using this approach see Charts and KPIs pinned where the team can see them for multi-source analysis. Analytics stops being a bottleneck and starts being a shared, everyday capability.
What looks like a tooling problem is often an access and trust problem in disguise. Every hour lost to messy csvs that break before any analysis begins is an hour not spent on the decision the numbers were meant to inform. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. Analytics stops being a bottleneck and starts being a shared, everyday capability.
Teams end up waiting on the BI queue instead of exploring the data themselves. Over time, messy csvs that break before any analysis begins translates into slower reporting, duplicated work, and insight that never reaches the people who need it. Every hour lost to messy csvs that break before any analysis begins is an hour not spent on the decision the numbers were meant to inform. The result is charts and kpis pinned where the team can see them, without adding headcount or waiting on the queue. You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. Analytics stops being a bottleneck and starts being a shared, everyday capability.
The cost of messy csvs that break before any analysis begins is rarely a single number — it is decisions made late, on stale data, or on gut feel. What looks like a tooling problem is often an access and trust problem in disguise. Every hour lost to messy csvs that break before any analysis begins is an hour not spent on the decision the numbers were meant to inform. People using this approach see Charts and KPIs pinned where the team can see them for multi-source analysis. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see.