A Leadership View
Most questions about the numbers are simple; getting them answered rarely is. Expectations around analytics have shifted, and the tools people rely on have to keep up. The way a team works with its data says a lot about how quickly it can act. For fintech & payments, the difference between a fast decision and a stalled one often comes down to how quickly a simple question about the data gets a trustworthy answer. Every team has data in spreadsheets and exports — the hard part is turning it into answers without waiting on an analyst.
The Leadership Concern
It rarely starts as a crisis; waiting on a data pipeline before anyone can look builds quietly until a board deadline makes it impossible to ignore. A recurring challenge for fintech & payments is waiting on a data pipeline before anyone can look. Left unaddressed, waiting on a data pipeline before anyone can look compounds: questions pile up, reports go stale, and insight stays locked away. For a Growth Marketer, waiting on a data pipeline before anyone can look is more than an inconvenience — it is a daily drag on how fast the team can move.
Operational Risk
For leaders, the real risk is strategic: an analytics bottleneck becomes a ceiling on how fast the business can learn. Every hour lost to waiting on a data pipeline before anyone can look is an hour not spent on the decision the numbers were meant to inform. What looks like a tooling problem is often an access and trust problem in disguise. Over time, waiting on a data pipeline before anyone can look translates into slower reporting, duplicated work, and insight that never reaches the people who need it.
Team Expectations
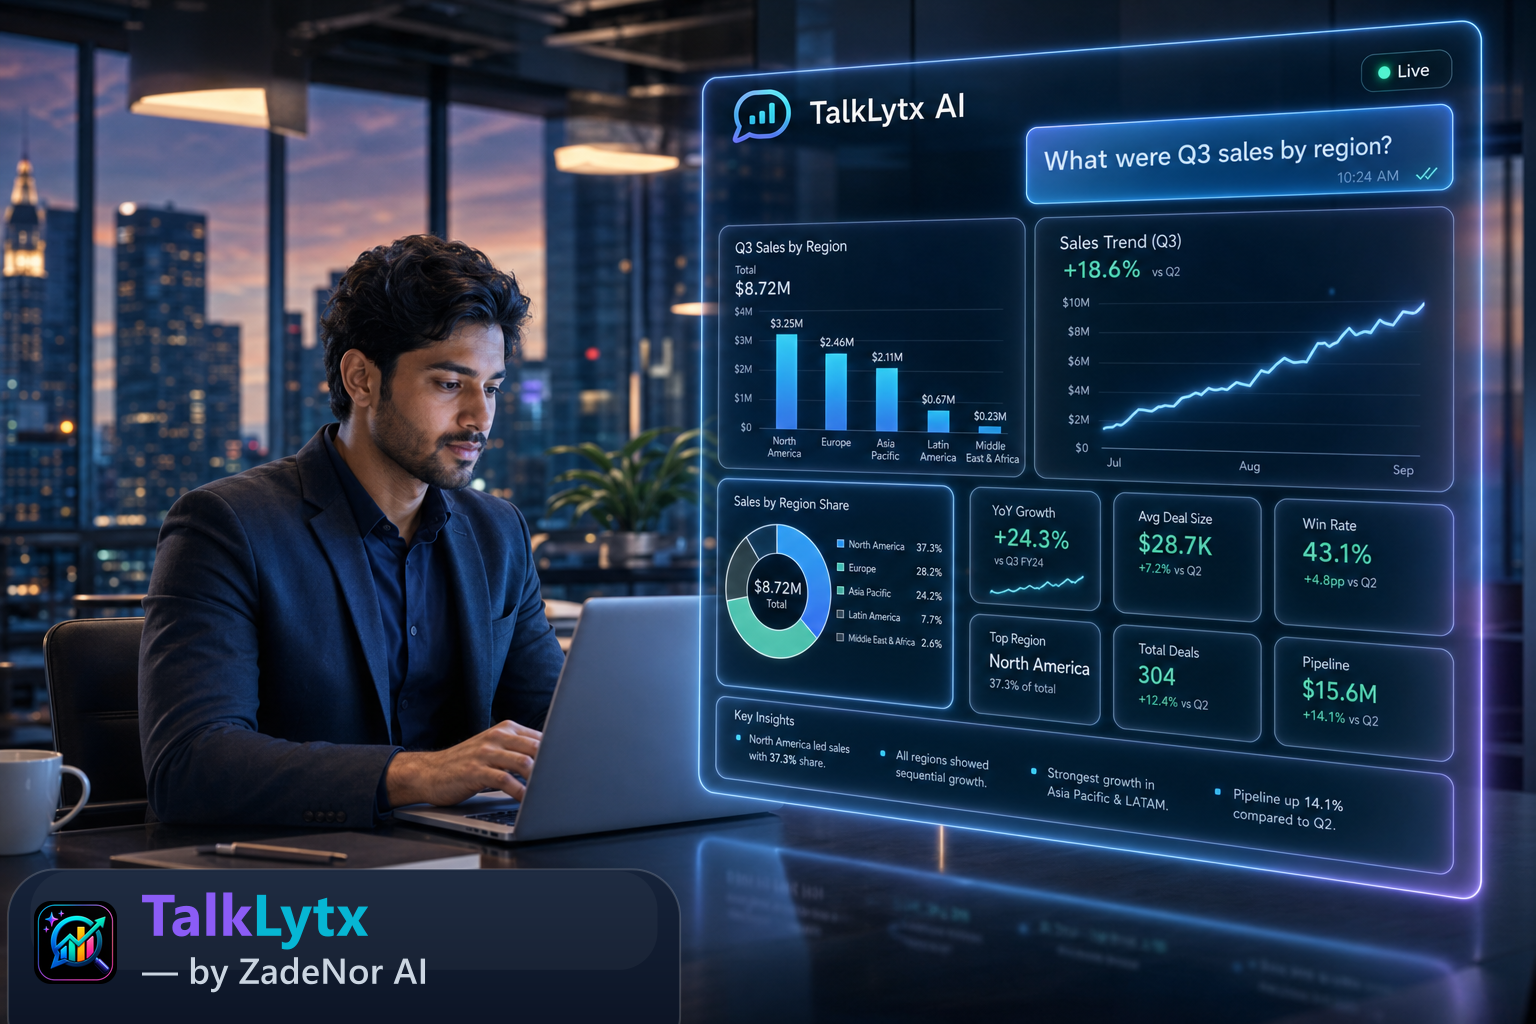
People now expect to ask a question in plain English and get an answer, a chart and the SQL — without learning a query language. They want to know not just the number, but the logic behind it, with SQL they can view and edit. Self-serve analytics is the new default; people want to explore the data themselves, not file a request. The modern standard is simple: upload or connect, ask, and get an answer in seconds. Anything a tool cannot answer quickly, or explain transparently, now feels like a risk.
How TalkLytx Helps
Since read-from-URL data feeds sits within the Platform capability set, it fits naturally into how fintech & payments already work. This is where TalkLytx comes in — the conversational data-analytics platform built by ZadeNor AI. Rather than another BI tool to learn, TalkLytx lets you upload a file or read from a URL and simply ask your question in plain English. Because the answer, the SQL and the chart arrive together, you work from one transparent source of truth instead of a black box.
Strategic Recommendation
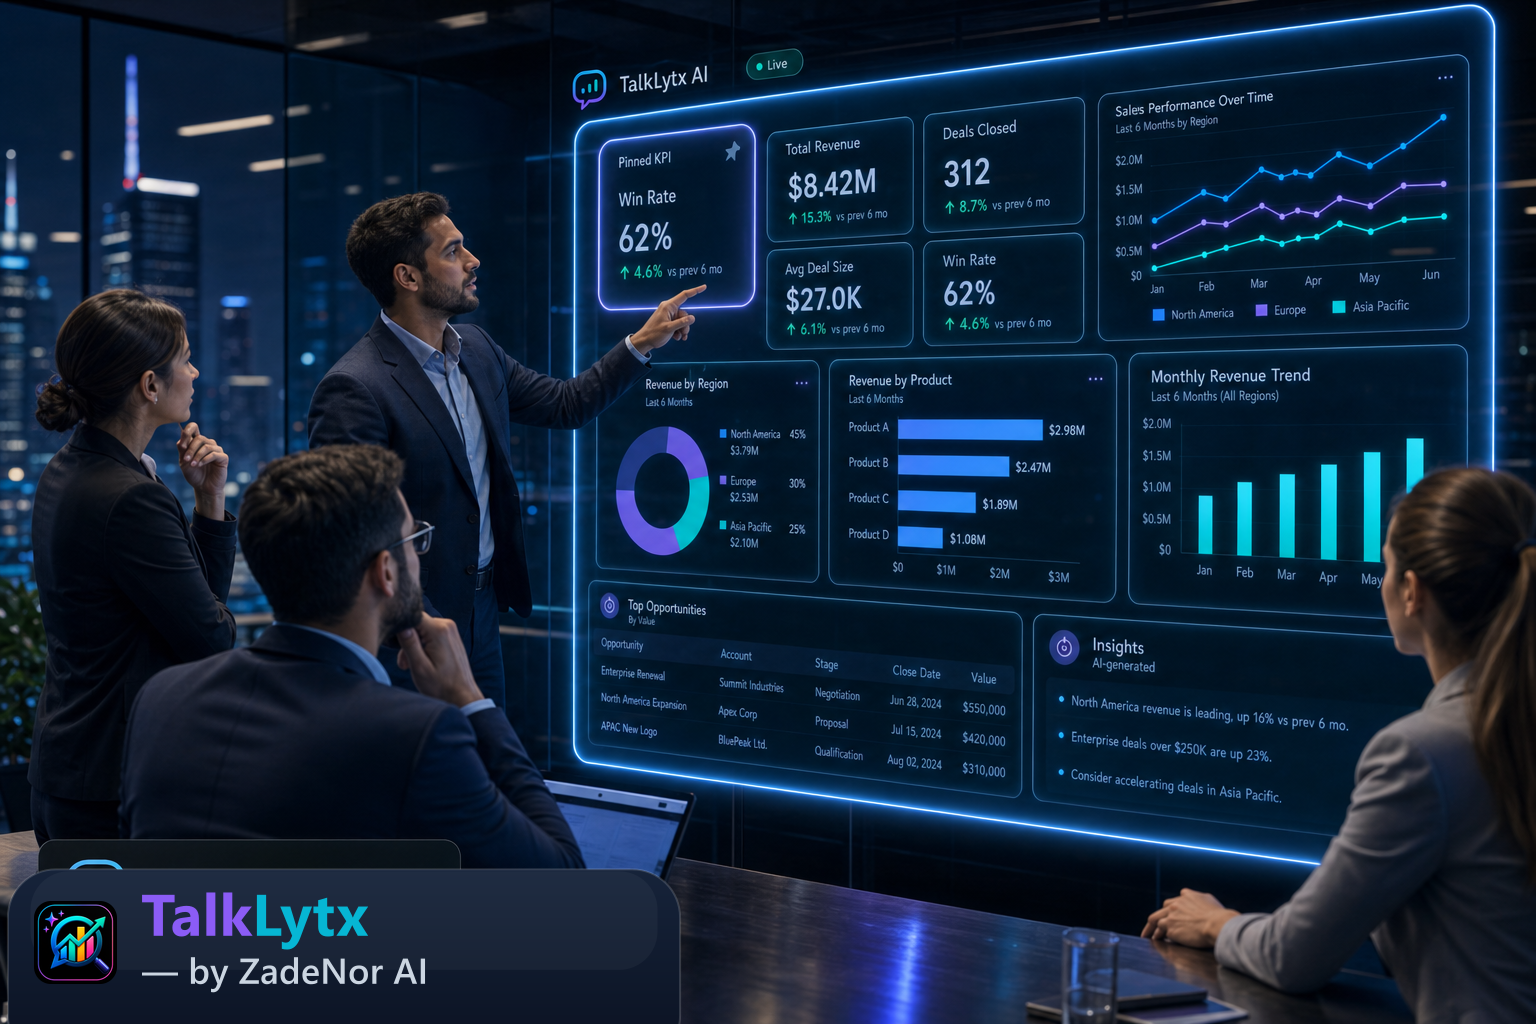
Pilot TalkLytx on one recurring report and let the team pin the KPIs they check every week. The practical move is to put your everyday files in one place and let plain-English questions and instant charts do the heavy lifting. Start where the queue is longest — that is where self-serve, conversational analytics pays off fastest. Give the team a workspace that scales with its questions instead of its analyst headcount. Treat transparent, editable SQL as a trust lever, not a technicality, and tool it accordingly.
Expected Outcomes
You get a calm, self-serve analytics workspace; decisions get faster and every team can answer its own questions. Analytics stops being a bottleneck and starts being a shared, everyday capability. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see.
Next Steps
From a raw file to a pinned dashboard, TalkLytx by ZadeNor AI keeps Fintech & Payments analytics fast, transparent and self-serve. Launch TalkLytx and get your first answer in minutes.
The cost of waiting on a data pipeline before anyone can look is rarely a single number — it is decisions made late, on stale data, or on gut feel. Teams end up waiting on the BI queue instead of exploring the data themselves. Every hour lost to waiting on a data pipeline before anyone can look is an hour not spent on the decision the numbers were meant to inform. People using this approach see From raw file to decision in minutes for self-directed users. The numbers follow the rigour: fewer ad-hoc requests, faster reporting cycles, and insight everyone can see. For fintech & payments, that means from raw file to decision in minutes you can actually rely on.
The cost of waiting on a data pipeline before anyone can look is rarely a single number — it is decisions made late, on stale data, or on gut feel. Every hour lost to waiting on a data pipeline before anyone can look is an hour not spent on the decision the numbers were meant to inform. For fintech & payments, that means from raw file to decision in minutes you can actually rely on. People using this approach see From raw file to decision in minutes for self-directed users. Analytics stops being a bottleneck and starts being a shared, everyday capability.